Gemini 3.8 Live Makes Voice Agents More Useful—and More Operationally Demanding
Google’s Gemini 3.8 Live brings background tool calls, live visual input and native speech-to-speech interaction to voice agents. The practical question is no longer whether it can talk, but whether a team can control latency, permissions, data retention and failure recovery.
Google’s Gemini 3.8 Live is a meaningful release for voice-agent builders because it changes the interaction model, not just the voice quality. The model is designed to listen and speak directly, accept live visual context, and call tools asynchronously while the conversation continues. That last detail is the important one: a voice agent can acknowledge a request, keep the user oriented, and wait for a backend operation without falling silent or forcing the user through a rigid turn-taking script.
Google announced the developer models on September 15, 2026. On September 24, Google Cloud said Gemini 3.8 Live with Live Avatar was generally available in Gemini Enterprise, with US and EU endpoints, provisioned throughput, enterprise compliance and data-governance controls. The API model and the enterprise avatar product are related, but they are not the same deployment decision. A developer can experiment with the Live API; an organization still has to decide what the agent may hear, see, remember and do.
The practical advice is to treat Gemini 3.8 Live as a new interface layer for carefully bounded workflows, not as a universal replacement for chat, forms or human service. It is a strong candidate for guided intake, coaching simulations, field assistance, troubleshooting and other situations where speaking is faster than typing. It is a poor fit for any process that treats a fluent voice as evidence that the underlying decision is correct.
What actually changed in Gemini 3.8 Live
The release combines several capabilities that used to be assembled as a chain: speech recognition, a text model, tool orchestration and speech synthesis. Google describes Gemini 3.8 Live as an audio-to-audio model optimized for real-time dialogue. Its model documentation lists audio generation, Live API support, function calling, search grounding and interleaved thinking. It does not list code execution, file search, URL context or structured outputs as native capabilities of this model.
That boundary matters. A voice agent is not automatically a general-purpose agent simply because it can call a function. The application still supplies the tools, validates their arguments, handles authorization, returns the result and decides what can happen without confirmation. Gemini can request a function call; the application owns the consequences.
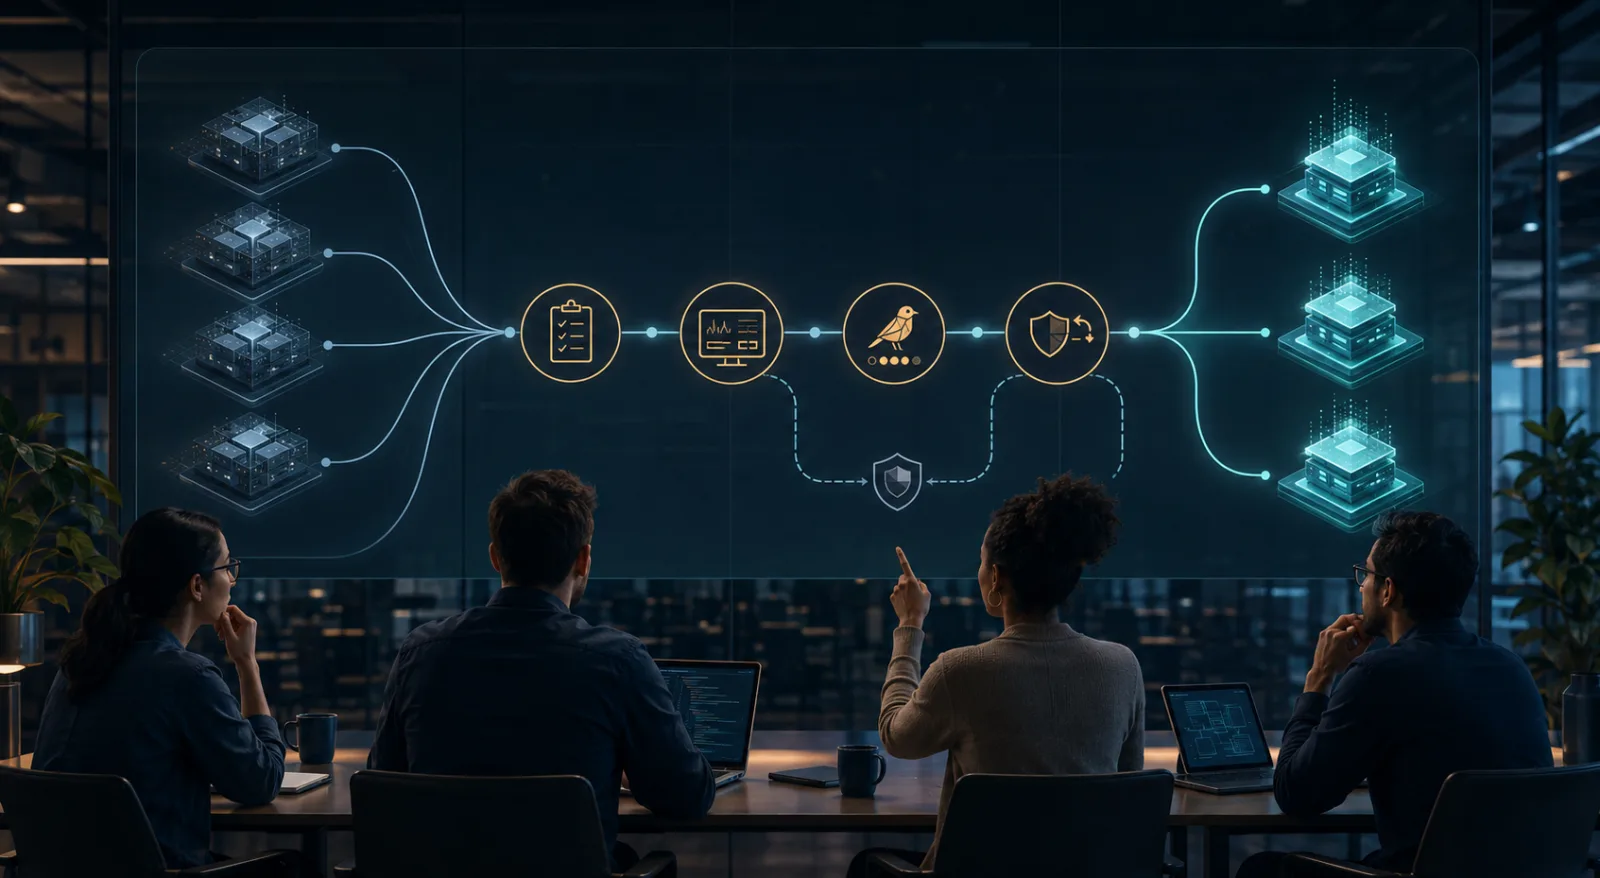
The most visible product change is asynchronous function calling. A tool can run in the background while the model keeps the conversation moving. Imagine an insurance intake agent that asks a customer to describe damage while a service checks policy details. Or a field-support assistant that listens to a technician while retrieving the correct maintenance procedure. Or a training simulator that lets a learner practice a difficult conversation while the system scores events in the background.
Google also highlights live visual understanding. The agent can use audio together with a camera feed or screen share. In a claims workflow, the user might show a damaged component while explaining what happened. In technical support, a worker might point a camera at a panel or share a software screen. This is useful because the user does not have to translate everything they see into a verbal description. It also creates a privacy problem: the microphone is no longer the only sensor in the system.
The model supports automatic language detection and Google says Gemini 3.8 Live can understand and speak 97 languages. That is useful for international products, but language coverage should not be confused with equal reliability across accents, dialects, noisy environments, specialized vocabulary and high-stakes terminology. A language can be technically supported while a particular workflow remains poorly evaluated.
The production use case is a workflow, not a demo
A convincing demo usually has one person, a clean microphone, a short session and forgiving inputs. Production voice systems encounter interruptions, background noise, code-switching, silence, accents, overlapping speech, ambiguous references and backend delays. The design target should therefore be a complete workflow with explicit state transitions.
Start by defining the smallest useful job. “Help customers with claims” is too broad. “Collect the incident date, location, policy identifier, visible damage category and preferred callback time, then create a draft case for human review” is testable. The narrower version gives the agent a clear stopping point, a finite tool set and an observable success condition.
A good first workflow has four properties:
- The user benefits from speaking or showing something rather than filling out a form.
- The agent can gather information without making a final regulated or irreversible decision.
- A human or deterministic service can verify the result.
- The organization can replay and evaluate failures without retaining more sensitive media than necessary.
This points toward intake, triage, coaching and assistance before autonomous action. The agent may prepare a case, find a document, draft a response or suggest the next step. It should not silently approve a payment, change a medical record, cancel a service or send an irreversible instruction merely because the voice exchange sounded confident.
Latency is a systems problem
Native speech-to-speech reduces the need to pass every turn through a visible transcription-to-text-to-speech pipeline, but it does not remove latency. Audio has to reach the service, the model has to decide whether to respond, a tool may need to run, and the client has to play the result. A good voice experience depends on all of those stages.
Google’s Live API guidance recommends sending small audio chunks rather than buffering a long segment. It specifically points developers toward chunks in the 20–100 millisecond range and recommends resampling microphone input to 16 kHz. These are implementation details with user-facing consequences. A client that waits a second before sending audio will feel sluggish even if the model is fast. A client that fails to discard already-buffered output after an interruption will talk over the user.
Interruption handling deserves its own test suite. When the user begins speaking while the model is replying, the server can signal that the response was interrupted. The client must immediately stop or discard queued audio. If it does not, the agent appears not to listen. That failure is more damaging in voice than in chat because users expect a spoken system to recognize ordinary conversational turn-taking.
Tool latency needs a separate interaction contract. The agent should not imply that an action has completed when it has only started. A useful pattern is to distinguish three states in plain language: “I’m checking that,” “I found the record,” and “I completed the change.” Those statements should map to actual backend states, not to the model’s guess about what probably happened.
Asynchronous calls are valuable precisely because the user can continue talking while work proceeds. They are also risky because the agent may collect new information that changes the meaning of the original request. The application should bind each tool call to a clear request identifier, validate arguments when the call arrives, and decide whether the result is still relevant before applying it. A calendar lookup can become stale. An inventory check can change. A payment authorization should never be inferred from conversational momentum.
Session length and context need active management
Real-time audio consumes context continuously. Google’s best-practices documentation says native audio tokens accumulate at approximately 25 tokens per second. Without context management, audio-only sessions are limited to 15 minutes and audio-plus-video sessions to two minutes; Google documents compression and resumption mechanisms for extending sessions.
This is not merely a quota issue. Long sessions create a memory problem. The agent needs the current task state, the facts that have been confirmed, unresolved questions and the latest tool results. It does not necessarily need every hesitation, repetition or background sound. Teams should define a compact state representation rather than assuming that a long transcript is a reliable working memory.
Context compression can preserve continuity, but compression is a lossy operation from the application’s perspective. Test what happens to names, numbers, negations, dates and corrections after a long exchange. A customer saying “No, Thursday, not Tuesday” should not be summarized as “appointment on Tuesday.” Numeric fields deserve a deterministic confirmation step even when the model reports high confidence.
Session resumption has privacy implications as well. Google’s zero-data-retention documentation says that if a session handle is generated for Live API reconnection, conversation state including text, audio and video can be retained for up to 24 hours. Teams that require zero data retention should not configure session resumption. That creates a direct tradeoff between seamless reconnects and the strictest retention posture. It should be documented as a product decision, not buried in transport configuration.
Cost is easy to underestimate
Google’s published Gemini API pricing lists Gemini 3.8 Live audio input at $0.005 per minute and audio output at $0.018 per minute on the standard paid tier. The same page also lists token prices for text and image or video inputs, as well as separate charges or limits for grounding. These figures are useful for a first estimate, but they are not the complete cost of a voice workflow.
A simple audio estimate for a ten-minute conversation with five minutes of model output would be roughly 5 minutes of input at $0.005 plus 5 minutes of output at $0.018, or $0.115 before other usage and infrastructure. That is a model-usage estimate, not a customer acquisition cost or a production bill. Real sessions may have two-way audio for nearly the whole duration, multiple retries, visual input, search grounding, tool services, logging, telephony, storage, monitoring and human escalation.
The cost behavior is different from a text chatbot. A user who pauses, repeats a question or leaves an open microphone can continue consuming audio input. A background visual stream may add usage without creating proportional value. A tool call that fails and is retried can create both backend cost and additional conversational time.
Before launch, measure cost per completed workflow rather than cost per conversation. Useful fields include session duration, audio minutes in each direction, number of interruptions, number of tool calls, tool retries, escalation rate, visual-input minutes and the percentage of sessions that reach a useful outcome. If a five-minute automated call still requires a human to repeat the entire intake, the headline model price is irrelevant.
Build a budget guardrail into the client and the server. The client can warn or end an idle session; the server can enforce maximum duration, maximum tool calls and a per-user spending limit. Those controls should remain effective if the model loops, a tool becomes slow or a user keeps the microphone open accidentally.
Privacy is broader than transcript retention
Voice agents handle raw audio, transcripts, inferred attributes, tool arguments and potentially images or screens. Each data type may have a different retention policy. The organization should decide whether it needs to store raw audio at all, whether transcripts can be redacted, how long tool results remain available and who can inspect session traces.
Google’s documentation distinguishes zero-data-retention behavior from features that require state. Live session resumption can retain conversation state. Google Maps grounding has its own storage rule: the documentation says prompts, contextual information and generated output may be stored for 30 days to create grounded results, and that this storage cannot be disabled when Maps grounding is used. A system handling sensitive location or customer data should not treat a general zero-retention setting as a blanket guarantee for every connected feature.
Consent should be designed into the first spoken exchange. Users should know that they are talking to an AI system, whether audio or video is being processed, what the system can do and when a human may review the interaction. Recording rules vary by jurisdiction and use case; the product team should obtain legal guidance rather than relying on a generic disclosure. The agent should not hide its synthetic identity behind a human name or imply that a person is listening when nobody is.
Minimize the tool surface. If an agent only needs to read an order and create a draft note, it should not have permission to issue refunds, edit account ownership or export a customer history. Use separate functions for reading, drafting, confirming and committing. Require explicit confirmation for consequential operations, and enforce authorization in the backend rather than in a prompt.
Screens and cameras require a stricter default than voice alone. A screen share can expose unrelated customer records, passwords, internal messages or tokens. A camera can capture bystanders and documents outside the intended frame. Give the user a visible capture indicator, provide a fast stop control and avoid retaining frames that are not needed for the task.
Voice quality is not the same as understanding
A fluent voice can conceal uncertainty. This is a known concern in real-time voice research. A 2026 study evaluating several production voice systems found that systems often acted on the words of an utterance while missing information carried by vocal delivery, such as tone or emotion. The finding does not mean voice agents are useless. It means teams should not assume that a natural-sounding response demonstrates that the model understood urgency, sarcasm, distress or hesitation.
For consequential workflows, translate important vocal signals into explicit, testable behavior. If a caller sounds distressed, the system may offer a human escalation, but it should not diagnose the person from tone. If a user hesitates before authorizing an action, the system should ask for clear confirmation instead of treating silence as consent. If a technician sounds uncertain about a part number, the agent should read it back and request verification.
Evaluation should include difficult audio, not only clean recordings. Test overlapping speakers, poor microphones, traffic noise, television audio, children speaking in the background, accents, fast speech, code-switching, low-volume speech and users who correct themselves. Add tests for alphanumeric strings, dates, decimal values, negation and similar-sounding names. For video, test occlusion, glare, motion blur, irrelevant objects and intentionally misleading views.
The scorecard should measure more than response latency and user preference. Track field-level extraction accuracy, false confirmations, missed interruptions, unsupported claims, unsafe tool calls, escalation quality, session recovery and cost per successful completion. A voice agent that is slightly less charming but never commits an unconfirmed action is usually the better production system.
How to structure a first pilot
A sensible pilot can be small. Choose one workflow with a clear owner and a measurable baseline. Record the current time to completion, abandonment rate, transfer rate, error rate and cost. Then compare the voice agent against that baseline using the same task definition. Do not compare a polished demo with an unstructured human process.
Use a read-only or draft-only mode first. Let the agent gather information, search approved sources and produce a structured draft. Keep a human approval step before external side effects. This gives the team real interaction data without making early model errors irreversible.
Create a test set from real workflow variation, but remove or protect personal data. Include common cases, edge cases, adversarial prompts and cases where the correct behavior is to stop. Make the stopping behavior visible: “I can’t verify that from this conversation, so I’m sending it to a specialist.” A refusal that routes the user well is more useful than a confident answer that keeps the call short.
Instrument every boundary. Log when the user began and stopped speaking, when the agent was interrupted, which tool was requested, what the backend returned, whether the user confirmed a consequential action and why the session ended. If raw audio is not required for debugging, do not retain it by default. If debugging requires it temporarily, set a deletion schedule before the pilot begins.
Run a failure review every week. Categorize failures as recognition, turn-taking, reasoning, tool selection, authorization, backend reliability, privacy or user-experience problems. Each category suggests a different fix. Better prompting will not repair a missing permission check. A larger model will not repair a microphone that clips numeric input. A faster model will not repair a workflow that has no safe stopping state.
Who should try Gemini 3.8 Live
Teams should consider a pilot when the work is conversational, repetitive and bounded; when the user has a reason to speak or show rather than type; when a backend can provide authoritative records; and when the organization can keep a human or deterministic approval step around consequential actions. Training simulations, guided intake, field support, appointment preparation and internal knowledge assistance are plausible starting points.
Teams should wait when the main value proposition is simply that the agent sounds human. They should also wait when the workflow depends on subtle emotional interpretation, when audio or video cannot be governed properly, when backend tools are not idempotent, or when the business cannot explain how a user reaches a human. Voice adds convenience, but it also adds an always-on sensory channel and a new class of failure that is harder to notice in a transcript.
The model is also not a universal alternative to a conventional interface. Forms are better for precise structured data. Chat is often better for reviewing long text, links and citations. A human is better when the user is distressed, the situation is ambiguous or the cost of a wrong action is high. The strongest product may combine these modes: voice for collection and navigation, a visible screen for confirmation, and a human for exceptions.
The decision to make now
Gemini 3.8 Live lowers the friction of building voice agents that can do more than answer questions. Asynchronous function calling, visual context and native speech-to-speech interaction make it easier to construct agents that stay present while work happens elsewhere. Google’s pricing makes small pilots accessible, and the API documentation provides concrete guidance for streaming, interruption handling, context compression and session recovery.
Those improvements move the bottleneck up the stack. The hard work is now defining the workflow, limiting permissions, handling uncertainty, measuring field-level accuracy and choosing what the system must never do. A team that starts with a narrow draft-only workflow can learn quickly. A team that starts with broad autonomy may discover too late that a natural conversation is not the same thing as a controlled process.
The right question is not whether Gemini 3.8 Live can hold a conversation. It can. The useful question is whether the surrounding product can tell the difference between listening, guessing, checking, waiting and acting—and can make each state visible to the person on the other end of the microphone.
Related articles
Cyber-capable AI is becoming a trusted-access security tool, not a chatbot
Gemini Flash Cyber, OpenAI Astra and Claude Mythos point to a two-tier AI market where vulnerability discovery and patching need access gates, logs and human review.
AI search has turned Reddit spam into a business risk
Reddit’s LLM-powered spam fight shows how answer engines are changing marketing: brands want AI recommendations, but fake community consensus can damage trust fast.
GitHub Copilot Is Retiring Four Models: A Practical Migration Plan
The October 2 cutoff affects more than chat menus. Teams should trace policy and client dependencies, replay accepted work, measure review effort and move through a controlled canary before changing defaults.
The iPhone 18 Pro’s variable-aperture camera is useful, but it is not a reason for everyone to upgrade
Apple’s iPhone 18 Pro adds a mechanical variable-aperture main camera, manual exposure controls, a new chip and better claimed battery life. Here is what those changes mean in ordinary photos, video, upgrades and buying decisions before full reviews arrive.
Comments
Sign in to comment.
No comments yet.