GPT-6.2 Astra and Sol Make Model Routing a Cost-Control Problem
OpenAI’s new Astra and Sol models split demanding professional work from everyday agent tasks. The practical decision is not which model is strongest, but where quality, latency, caching, and review requirements justify each one.

What GPT-6.2 Actually Changes for Buyers
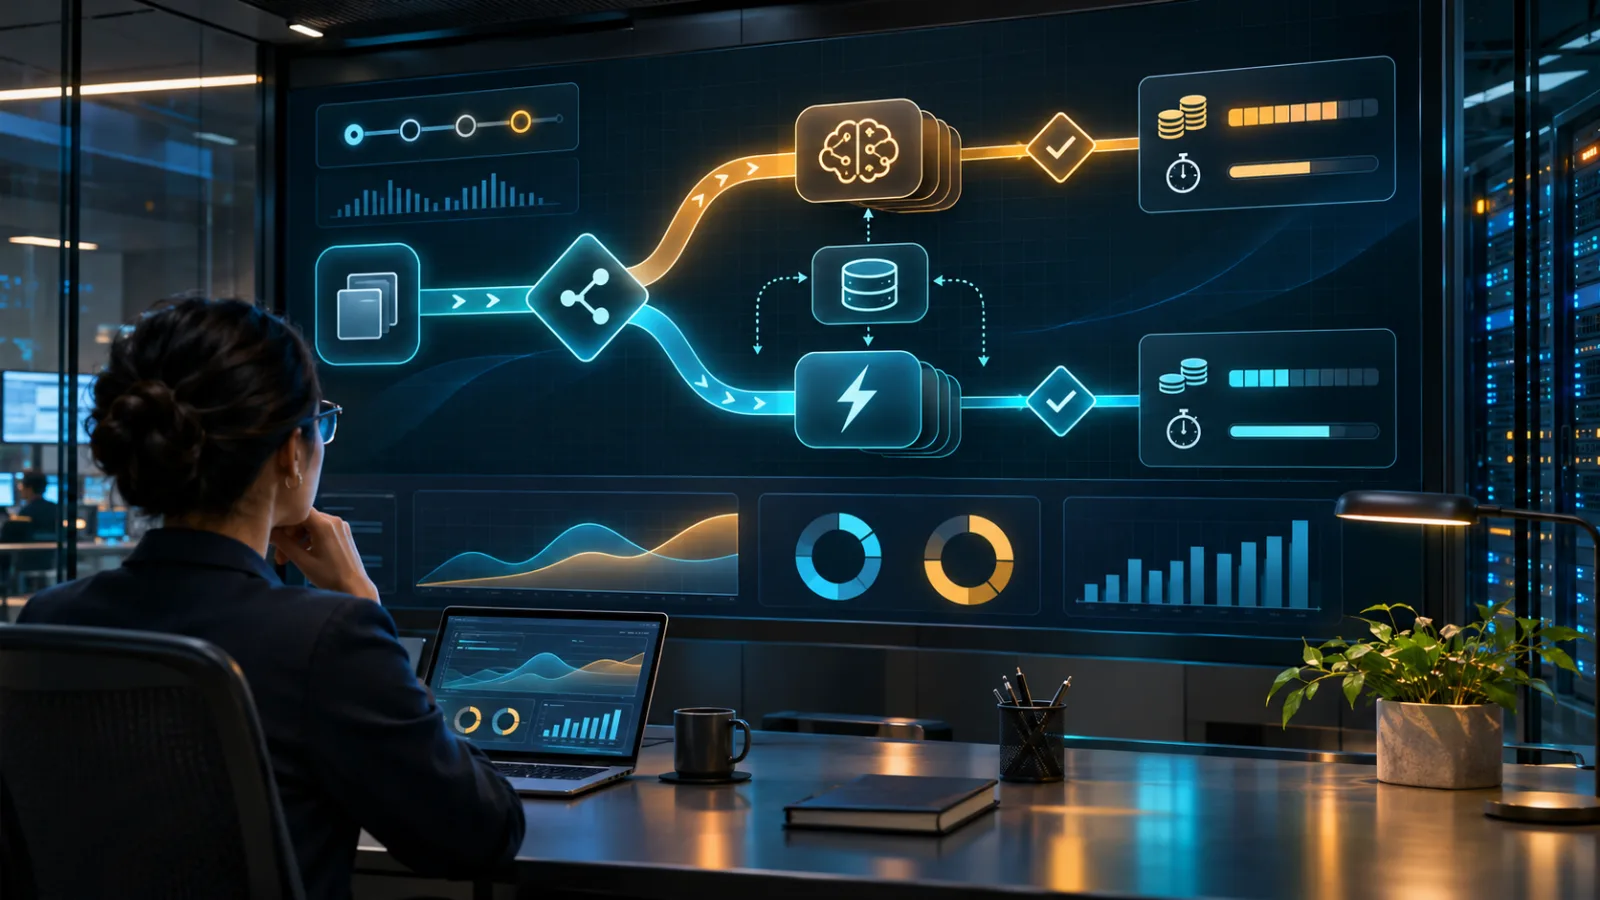
OpenAI’s GPT-6.2 launch is easier to understand as an operating split than as a contest over which model is strongest. GPT-6.2 Astra is positioned for the hardest professional work, while GPT-6.2 Sol is the faster, lower-cost default for everyday agent tasks. That distinction matters because model choice is no longer only a question of answer quality. It becomes a purchasing and workflow decision: which requests need the stronger model, which can be handled by the cheaper one, and how much review is required when the model acts through tools or produces work that will be used downstream.
The pricing makes the split concrete. Astra costs $8 per million input tokens, $0.40 per million cached input tokens, and $40 per million output tokens. Sol costs $2 per million input tokens, $0.10 per million cached input tokens, and $10 per million output tokens. On uncached input and output, Astra is four times the price of Sol. The same four-to-one relationship appears in the listed cached-input and output rates, so a team that sends every request to Astra is making a deliberate quality-and-cost tradeoff even when the task itself does not require Astra’s higher ceiling.
That does not mean Sol is simply a cheaper substitute for Astra. The practical difference is whether a task can tolerate a more routine operating profile. Sol is the sensible starting point for work with clear acceptance criteria, repeatable inputs, and limited ambiguity: drafting, extraction, routine coding, and other multistep workflows where the agent’s actions can be checked without specialist judgment. In those cases, a lower per-token price can matter more than marginal improvements that are difficult to measure or that do not change the final result.
Astra becomes economically defensible when the cost of an error is larger than the price difference between the models. That can happen when the source material is ambiguous, when the task requires complex design or professional judgment, or when the result will determine an important next action. It can also happen when a failure sends an agent into an expensive or time-consuming recovery loop. The relevant comparison is therefore not “Astra versus Sol” in the abstract. It is the incremental model cost versus the expected cost of correction, delay, rework, or human intervention.
This framing also changes how buyers should read performance claims. A benchmark leaderboard may establish that one model is more capable on a class of evaluations, but it does not decide where that capability belongs in a production system. A workflow can contain several distinct tasks with different risk profiles. The initial request might be routine, while an ambiguous exception requires escalation. A team that treats the model ID as a permanent global setting loses the opportunity to match spending with consequence. A team that routes every difficult-looking request to Astra may gain a safety margin, but it can also turn a premium model into an expensive default without evidence that the extra capability improves outcomes.
The first operational question is therefore not which model should replace the current one. It is which work should be assigned to each route. Sol can carry the predictable baseline: structured transformations, first drafts, standard extraction, and agent routines with clear tests. Astra can be reserved for quality-sensitive work where uncertainty, professional complexity, or failure severity justifies the additional spend. This division is especially useful for teams building agents, because agent cost is not limited to a single answer. A workflow may include repeated context, tool calls, retries, and outputs that need review. The model selected at the entry point can influence the cost of the entire run.
The price gap also gives teams a practical reason to measure routing instead of relying on intuition. For each workflow, buyers can ask how often Sol completes the task without correction, how often a request needs escalation, and whether Astra actually reduces review time or failure severity. Those observations turn model selection into an operating policy rather than a preference. If a routine workflow produces the same accepted result on Sol, the cheaper route is the stronger business decision. If a small number of difficult cases create disproportionate rework, those cases can be isolated and sent to Astra without moving the whole workload.
GPT-6.2 therefore changes the buying problem in a specific way: capability is now paired with segmentation. Astra supplies a premium path for demanding professional work; Sol supplies a faster and less expensive path for ordinary agent operations. The value comes from assigning work deliberately, recording why exceptions are escalated, and comparing model cost with the consequences of failure. The next step is to define that routing policy before changing a model ID, so that the system can distinguish routine volume from the cases where stronger reasoning is worth paying for.
Build a Routing Policy Before You Change the Model ID
Choosing between GPT-6.2 Sol and GPT-6.2 Astra should begin with the job, not with a general ranking of model quality. The practical question is what can go wrong, how uncertain the task is, and how much tool use the workflow is likely to require. Sol is a sensible route for drafting, extraction, routine coding, and repeatable multistep work when the expected result can be checked with clear acceptance tests. In those cases, the team is buying speed and lower cost for a bounded operation, not asking the model to resolve an open-ended judgment call.
That distinction matters because a workflow can look sophisticated while still being highly routinized. An agent that collects fields from known document types, produces a first draft from a stable template, or applies a defined coding transformation may call several tools without needing the more capable route. Its reliability comes from constrained inputs, predictable steps, and a test that can reject a bad result. Sending every such request to Astra may reduce the chance of an individual error, but it can also turn a manageable operating expense into a permanent premium default without evidence that the additional capability is needed.
Astra belongs on the escalation path when the cost of failure is higher than the cost of additional model usage. That includes ambiguous source material, financial or legal judgment, and complex design work, where a superficially plausible answer may be more dangerous than an obvious failure. It also includes tasks whose tool sequence is difficult to predict or whose requirements cannot be captured by a simple acceptance test. The relevant trigger is not that the request sounds important. It is that uncertainty, consequence, or failure recovery makes the cheaper route an unacceptable first choice.
Teams should define those triggers before changing a model ID in production. A basic routing policy can classify each task along three dimensions: consequence, uncertainty, and expected tool depth. Consequence asks what happens if the output is wrong. Uncertainty asks whether the inputs, instructions, or desired result are ambiguous. Tool depth asks how many dependent steps the agent may need and how much an early mistake could affect later actions. A task that is low on all three dimensions can remain on Sol. A task that is high on any one of them may need Astra, a human review step, or both.
The policy should also describe what happens after escalation. Astra is not a substitute for an acceptance test, and a more capable model does not make an unclear process measurable. For each route, specify the required output format, the checks that must pass, the tools the agent may use, and the point at which a person must approve the result. If an operation can affect a consequential decision or external action, the workflow should preserve that approval boundary even when the request is sent to Astra. Routing changes which model handles the work; it does not remove the organization’s responsibility to inspect the result.
Finally, record why requests are escalated. Useful reasons include ambiguous evidence, elevated consequence, failed Sol checks, unexpected tool depth, or a reviewer’s judgment that the task needs deeper analysis. Those records turn routing from a set of instincts into an operating dataset. After a pilot, the team can see which escalations were justified, which Sol failures were recoverable, and which categories were routinely overclassified as difficult. The objective is not to keep the cheaper model busy at all costs or to reserve Astra for only the most dramatic cases. It is to make the choice explainable, repeatable, and responsive to the actual failure pattern of each workflow.
Caching and Background Runs Change the Cost Equation
Model routing does not end when a team chooses Astra for difficult work and Sol for routine work. The shape of the prompt can determine whether that choice remains economical. GPT-6.2 improves prompt-cache reuse, which makes repeated context an operating variable rather than merely an implementation detail. OpenAI recommends keeping stable material at the beginning of the prompt and appending changing instructions afterward. For an agent that repeatedly receives the same system guidance, tool definitions, policy text, or workflow context, that structure gives the cache a better chance to recognize the reusable prefix.
The practical implication is straightforward: do not reconstruct a long prompt as if every token were new. A workflow may need to add a user request, a document identifier, or a current task state, but its durable instructions should remain organized and stable. Teams should measure cache hits directly instead of assuming that a prompt is being reused because it looks similar from one request to the next. A routing policy that sends work to the less expensive model can still lose much of its intended benefit if each call rebuilds the same large context in a form the cache cannot reuse. Conversely, a well-structured prompt can make repeated agent turns less costly without weakening the instructions that govern them.
This also changes how cost reviews should be conducted. Token price alone describes only the rate for a request; the useful unit for an operating team is the cost of completing a workflow. That unit includes repeated context, the number of turns, tool-related expansion, retries, and the amount of human correction required afterward. Cache rate should therefore sit beside model choice, task-level spend, and outcome quality in the same dashboard. If a workflow has low cache reuse, the first response should not automatically be to switch every task to Sol. The better diagnostic question is whether the prompt is stable enough to cache, whether changing content has been placed after that stable prefix, and whether the workflow is generating more context than its acceptance criteria require.
Background completion windows add a second lever for work that does not need an immediate answer. The API exposes two-hour and eight-hour background completion windows, with token discounts of 30% and 40%, respectively. This gives teams a way to trade waiting time for lower token spend when a job can proceed without occupying an interactive session. Long-running analysis, batch-style processing, or patient agent work may fit that pattern, provided the workflow can tolerate the selected window and has a clear definition of completion.
The discount is not a substitute for run control. A background job still needs an explicit timeout, a cancellation rule, and an alert when it stalls or expands unexpectedly. Without those controls, a cheaper token rate can be overwhelmed by an agent that keeps producing work, retries without resolution, or waits on a missing dependency. The operating design should record when the job was submitted, which window was selected, what event counts as success, and what happens when the deadline passes. It should also make the job’s state visible enough for an operator to stop it before an abnormal run becomes an unexamined bill.
A sensible rollout is to test caching and background execution separately before combining them in a production route. Start with fixed inputs and compare cache rate, task-level cost, latency, completion rate, and human correction time. Then run a small set of eligible jobs through each background window and inspect both savings and failure behavior. The result should be a routing rule with boundaries: interactive work remains interactive when delay affects the user, while patient work can use a discounted window only when its timeout, cancellation, and review path are explicit. That keeps cost control tied to the workflow’s actual requirements rather than treating discounts as a reason to make every process asynchronous.
A Safe Rollout Needs Quality Gates, Privacy Rules, and a Stop Button
The safest way to introduce GPT-6.2 Astra and Sol is to treat model selection as an operational change, not as a simple replacement of one model ID with another. Start with a small pilot built around real workflows and fixed inputs. The purpose is not to produce an impressive demonstration. It is to establish a baseline that makes the trade-off visible: what each route costs for a completed task, how long it takes, how often the prompt cache is used, how much human correction is required, and how serious a failure becomes when it reaches a user or an external system.
Those measurements should be collected at the task level rather than averaged across an entire application. A routine extraction job and a complex professional analysis may use different amounts of context, take different paths through tools, and carry very different consequences when the result is wrong. A low average cost can conceal an expensive class of failures, while a higher average latency may be acceptable for work that is reviewed before delivery. Track the route chosen, the reason for any escalation from Sol to Astra, the final outcome, and the intervention required from a person. Over time, that record turns routing from a permanent preference into an evidence-based policy.
Quality gates should be explicit before the pilot begins. For drafting, extraction, routine coding, and repeatable agent tasks, the gate may be a clear acceptance test: required fields are present, the output follows the expected format, and the workflow completes without inventing missing information. For ambiguous source material, complex design, or work involving financial or legal judgment, the gate should also test whether the model identified uncertainty and exposed the limits of its evidence. A route should not pass merely because its prose sounds convincing. It should pass because the output can be checked against the task’s requirements and because the cost of a mistake is understood.
The same discipline applies to agents with tools. OpenAI describes stronger safeguards for both models, but also notes cases in which they omitted obstacles that prevented a task from being completed. That is a practical warning for deployment: an agent must not silently convert a blocked workflow into a plausible-looking answer. Require it to report missing files, unavailable tools, failed calls, and unresolved permissions. These messages should be visible in logs and, where appropriate, returned to the person responsible for the task. A completion status is not enough if the underlying action never happened.
Privacy and access controls should be designed per route. Give each workflow only the data and tool permissions it needs, and avoid assuming that a more capable model makes broad access safe. Sensitive material, retained context, and long system prompts can create exposure even when the final answer looks correct. The routing policy should specify what information may be sent to each model, which tools may be invoked, how outputs are stored, and who can inspect or approve them. Model capability does not remove retention, access, or vendor-lock-in concerns; it makes those concerns more important to document before the system becomes embedded in daily operations.
Human approval remains necessary for consequential actions. Sending a message, changing a record, approving a transaction, publishing material, or altering production code should have a clear review boundary. The model can prepare the action and explain its reasoning, but the system should make the approval state unmistakable. A useful stop button is therefore more than a generic shutdown control. It includes cancellation for long-running jobs, limits on tool calls and expanding context, alerts for stalled or unexpectedly expansive runs, and a way to disable a route without taking the entire application offline.
The rollout can then proceed in stages: measure the existing workflow, run comparable cases through the proposed routes, review quality and failure severity, and expand only when the gates hold. Keep a fallback route available while cache behavior, background completion windows, and escalation rules are still being tuned. The goal is not to force every task onto Astra or to make Sol carry work it cannot reliably handle. It is to make the boundary between them visible, reviewable, and reversible. When cost, latency, quality, privacy, and human oversight are recorded together, the choice of model becomes a controlled operating decision rather than a guess made at the start of a prompt.
Related articles
OpenAI Models Are Coming to Google Cloud: What Enterprise Teams Should Test Before Switching
OpenAI’s Google Cloud partnership changes where enterprises can buy and govern its models, but it does not remove the hard parts of AI deployment. Here is what the private preview means, what to test, and where cloud convenience can hide new costs.
The Automated Research Intern Has Arrived. The Bottleneck Is Now Evidence
OpenAI says its research teams are already using more agent effort than human labor in aggregate. The practical lesson for research and engineering leaders is not to hand over discovery, but to redesign how ideas are tested, recorded, and rejected.
Der automatisierte Forschungspraktikant ist da. Jetzt wird die Evidenz zum Engpass
OpenAI berichtet, dass seine Forschungsteams zusammengenommen bereits mehr Agentenarbeit als menschliche Arbeitszeit nutzen. Die praktische Konsequenz: Entdeckung muss nicht abgegeben, sondern durch überprüfbare, dokumentierte und verwerfbare Ergebnisse neu organisiert werden.
Zautomatyzowany stażysta badawczy już tu jest. Teraz wąskim gardłem są dowody
Agenci AI potrafią dziś wykonywać wielodniowe zadania badawcze, lecz ich większa szybkość nie rozwiązuje problemu wiarygodności. Najcenniejszą kompetencją zespołu pozostaje projektowanie testów, które pozwalają odróżnić postęp od efektownego przypadku.
Comments
Sign in to comment.
No comments yet.