Oracle’s Deep Trust AI Architecture Moves Agent Controls Below the Model Layer
Oracle’s new enterprise AI blueprint treats the database as the enforcement point for permissions, business rules and governed agent access. The practical question is whether that promise justifies deeper commitment to Oracle’s data and application stack.
What Oracle announced, and why the database is the center of the pitch
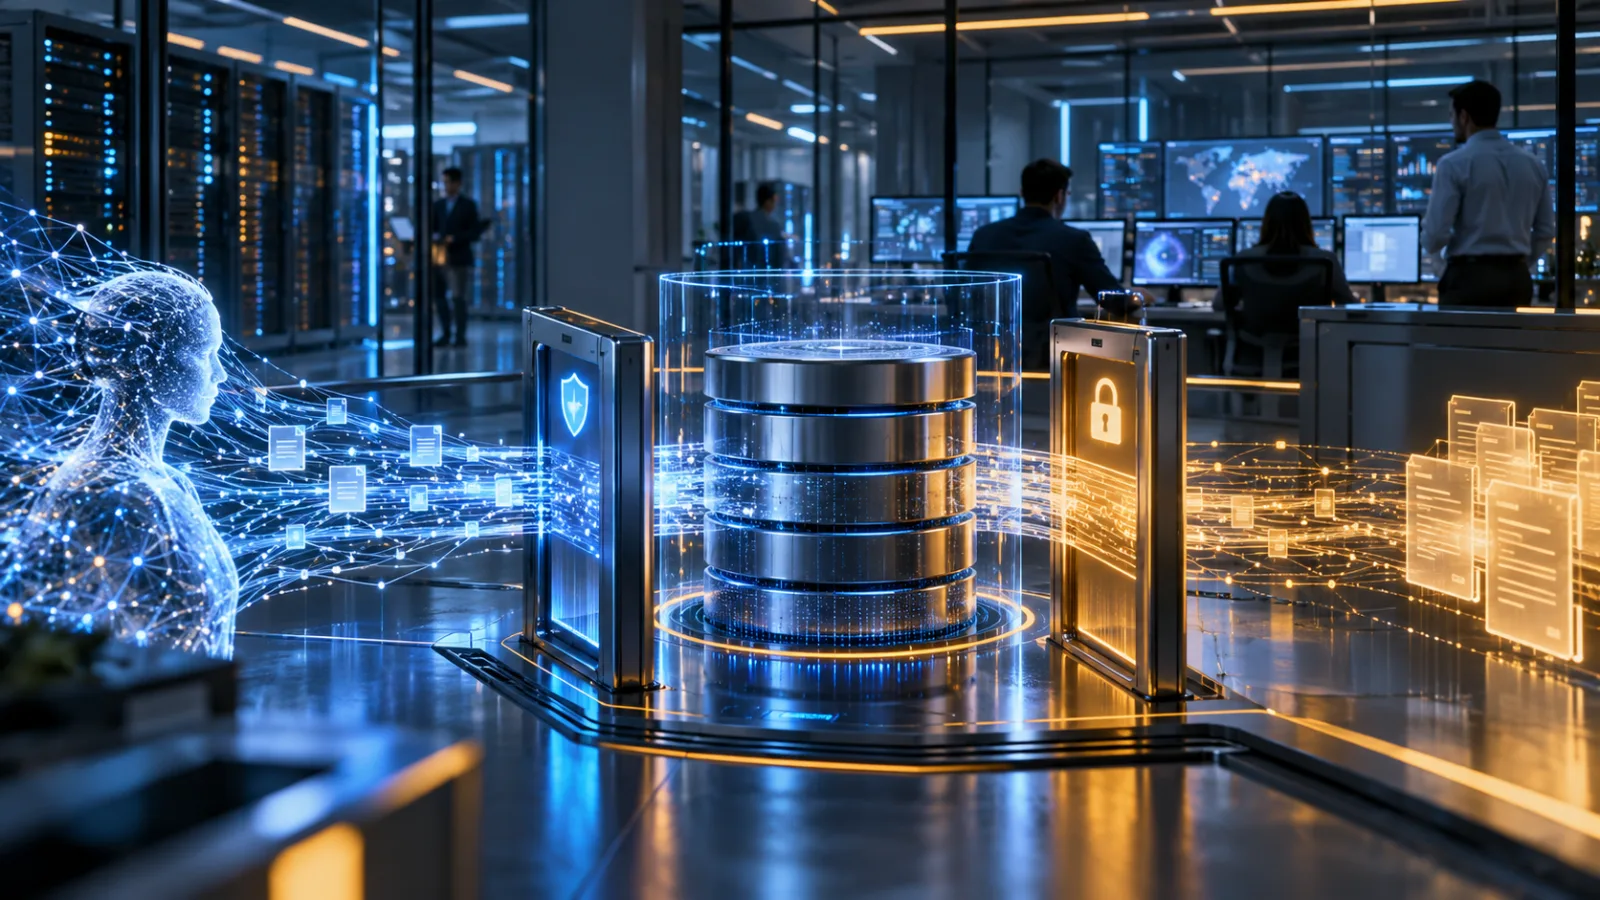
Oracle’s October 26 announcement presents Deep Trust AI Architecture as a four-layer blueprint for enterprise AI: the software platform, data, data access, and application development. That framing matters because Oracle is not positioning the announcement as a new foundation model or as a standalone safety product. Its central proposition is architectural. The controls that determine who may see or change information, and the rules that determine whether a transaction is valid, should remain attached to the enterprise platform and data rather than being left solely to an AI model, an agent framework, or an individual application.
The practical concern behind that proposition is straightforward. An enterprise agent may reach the same information through a chat interface, an analytics workflow, an application, an API, or a generated piece of software. If authorization and business logic exist only in one of those entry points, a new path can create a gap. A model may produce an unsafe instruction, an agent may misinterpret a request, or a developer may expose a broader query than intended. Oracle’s pitch is that the database and surrounding platform should continue to enforce the relevant boundaries when those paths change. In that design, an agent is a caller subject to enterprise controls, not an authority that gets to redefine them.
That is the distinction between a model-centric promise and a data-centric control plane. A model can be instructed to avoid revealing a sensitive value, and an agent can be configured to request approval before taking an action. Those safeguards may be useful, but they are coupled to the behavior of the model and to the completeness of the application that invokes it. Oracle’s Deep Trust framing moves the decisive question lower in the stack: when a request reaches governed data or an operation reaches a governed business object, what policies are applied at the enforcement point? The answer is intended to persist even when the request comes from an AI-assisted application rather than from a conventional user interface.
Oracle describes the architecture as spanning four connected layers. The software-platform layer supplies the broader environment in which enterprise applications and AI capabilities operate. The data layer is where the information and its security context reside. The data-access layer is meant to mediate how that information is exposed, including controls that can distinguish a permitted business operation from unrestricted access to underlying records. The application-development layer addresses how teams create and maintain software that may itself be produced or modified with AI assistance. Taken together, the layers form a claim about continuity: the same enterprise policies should apply across the route by which data is accessed and the method by which an application is built.
This also explains why the database sits at the center of the announcement even though the subject is AI. The database is a common point beneath many applications, reports, integrations, and agentic workflows. If authorization can be enforced at row, column, or cell scope, and if business constraints can be represented declaratively near the data, those controls have a chance to travel with the information instead of being reimplemented separately in every interface. Oracle’s associated documentation describes this direction through Deep Data Security, SQL Assertions, and Trusted Data APIs: mechanisms that place data authorization, declarative rules, and governed business-object access in the database and data-access layers.
The promise should still be read as an architectural direction, not as evidence that every risk has disappeared. Moving enforcement below the model can reduce dependence on a model’s instructions, but it does not by itself answer whether identities are mapped correctly, whether policies express the business’s intent, or whether an agent has been given more authority than its task requires. Nor does a database-centered design automatically make generated applications safe. It changes where teams can inspect and enforce important decisions. The value therefore depends on whether those decisions are consistent across applications, observable in audit evidence, and testable under the kinds of mistakes an enterprise agent is likely to make.
For buyers, the announcement is best understood as a proposal to make the data platform the durable boundary around AI-enabled work. That proposal may be especially relevant where sensitive relational data already lives in Oracle and where existing applications or development teams can use the same platform controls. It is less persuasive as a generic reason to adopt Oracle without testing the surrounding commitments. The questions are not limited to whether an agent can produce a useful answer. They include whether the agent can be prevented from crossing a row or cell boundary, whether a business rule still blocks an invalid write, and whether a new AI-generated application must pass through governed interfaces before it can act. Those tests lead directly to the mechanisms Oracle documents, which determine whether the four-layer architecture is an enforceable operating model or primarily a high-level blueprint.
The controls that could survive an agent’s mistakes
Oracle’s Deep Trust AI Architecture is most consequential as a control-plane proposal, not as another model announcement. Its practical promise is that permissions and business rules remain attached to the data and application layers even when access is mediated by an agent, analytics tool, or generated application. That matters because an agent can reach the same business information through a new prompt, tool call, or application path. If authorization exists only in model instructions or one front-end workflow, each new route creates another chance to bypass it. Oracle’s approach places enforcement closer to the database and the governed interfaces around it.
The first mechanism is Deep Data Security, which Oracle describes as supporting authorization at row, column, and cell level. That is more precise than a simple table-level allow-or-deny rule. An employee expense system might let an agent read a user’s own submissions while blocking other employees’ records. A finance role might see an expense amount and approval status but not a sensitive identifying field. The policy can therefore be evaluated against the specific data item requested, rather than only against the application or table. Oracle says the database verifies the user’s identity from a cryptographically signed token issued by the corporate directory and enforces the resulting rules regardless of which application or agent makes the request.
That is directly relevant to agent failures. An agent asked to find an employee’s reimbursement history may misunderstand the request, select an overly broad tool, or construct a query that asks for more information than necessary. Data-layer controls can constrain the result at the enforcement point, so the mistake does not automatically become a disclosure. They do not make the agent’s reasoning reliable; they limit the consequences when that reasoning is wrong. The same principle applies to a sensitive employee record: a model can propose a broad lookup, but the database should still return only the rows, columns, or cells permitted for the requesting identity.
SQL Assertions address a different problem: an action that is authorized in general but invalid under a business rule. Oracle gives spending limits as an example. An assertion can enforce the limit directly in the database, so if an application or agent attempts to charge more than the employee’s authorized amount, the database rejects the charge. Authorization and validity are separate checks: an agent may be allowed to update an expense record while still being unable to create an invalid approval or reimbursement state. This matters more as agents gain write access, because a bad write can alter financial, operational, or personnel records rather than merely return an incomplete answer.
Trusted Data APIs provide the interface-level complement. Instead of granting unrestricted SQL access and expecting an agent to discover the data model safely, they expose controlled read and write access to logical business objects, such as a complete purchase order. The database can then enforce update rules, integrity, and the object’s allowed evolution. A governed operation might retrieve permitted expense details or submit a reimbursement for validation, while keeping control over fields, relationships, and possible writes. That narrows the action surface and gives reviewers a clearer contract than a stream of generated queries.
A useful evaluation should deliberately test mistakes: request a sensitive employee field without the required access, ask for expenses across an organizational boundary, then attempt a reimbursement above its limit or an over-broad write. The system should return only authorized data, reject the invalid transaction, and behave consistently when the request arrives through an application, analytics workflow, or agentic interface. The strongest claim here is not that AI becomes safe by itself. It is that a model’s mistake need not become a database fact: data security can limit what an identity sees, assertions can prevent disallowed states, and trusted APIs can reduce what an agent is able to attempt. Identity design, policy maintenance, logging, data-quality checks, and human approval for consequential changes still remain necessary.
APEXlang changes the review surface for AI-generated applications
Oracle’s APEX 26.1 documentation presents APEXlang as a readable, versionable representation of an APEX application that AI coding agents can generate or modify. That changes the review surface for AI-assisted development: instead of treating an agent’s output only as an opaque sequence of prompts, tool calls and generated files, a team can inspect an application artifact in a form intended to describe the application itself. The representation can be stored, compared across revisions and reviewed before it is introduced into an environment. In an Oracle-centered workflow, that gives engineering and governance teams a concrete object to examine alongside the request that produced it and the identity under which it was produced.
The distinction matters because an application is more than its visible screen. A generated change may alter navigation, page behavior, data queries, processes, validations or other configuration that affects what users can see and do. A readable representation makes those changes easier to discuss in ordinary review language: which page was added, which process was changed, which data source is referenced, and which behavior is being introduced. Versionability also makes it possible to compare a proposal with the existing application and return to an earlier known state when a generated modification is unsuitable. That is useful operational discipline, but it should not be confused with proof that the application is safe. A clean diff can still describe a flawed authorization rule, an unsafe query, a misleading validation or a workflow that permits an unintended business action.
Oracle’s documentation also describes SQLcl’s apex validate command as part of the workflow for checking APEXlang before import. In practice, that places a machine-checkable gate between generation and deployment. The gate can help establish whether the artifact is structurally acceptable and can be processed through the expected APEX workflow before a team commits it to an application environment. It is especially useful when an organization wants agents to propose changes without giving them an unrestricted path to publish those changes directly. The important control is not merely that an agent can generate an application; it is that the generated representation can be inspected, validated and deliberately admitted.
That review model still leaves several questions for the implementation team. Validation of the representation does not establish that the requesting identity should be allowed to make the change, that the referenced data is appropriate for the use case, or that the resulting behavior complies with business policy. It does not replace testing of authorization schemes, checks for unintended data exposure, or verification that an agent cannot turn a narrowly scoped request into a broader write. Teams should test the same artifact under different identities and roles, including a user who may view a record but not modify it and an agent that has permission to perform one business operation but not another.
The artifact also needs review for data quality and operational consequences. A generated page can be syntactically valid while presenting stale, incomplete or incorrectly joined information. A generated process can be valid while producing a duplicate, skipping an approval or changing a record outside the intended scope. Those cases require test data, expected outcomes and a clear owner for approval. For consequential changes, human review remains necessary even when the proposed application is readable and the import process is validated. The practical value of APEXlang is therefore best measured as improved visibility, comparison and control over AI-generated application changes—not as an autonomous substitute for threat modeling, identity testing, data-quality checks or accountable release decisions.
Who should test it—and the lock-in questions to answer first
Oracle’s Deep Trust AI Architecture is most relevant to enterprises that already depend on Oracle databases, Oracle applications or Oracle’s low-code development stack, and that now want agents to read and change business data under enforceable controls. It is also a plausible candidate for organizations handling sensitive relational records, where an agent’s access cannot be governed only by a prompt, a model policy or an application developer’s intent. Existing APEX teams deserve particular attention because APEXlang adds a structured review surface for AI-generated application changes, while database-level controls can provide a common enforcement point across applications, analytics and agentic systems.
That does not make the architecture a default choice for every AI program. The first question is whether the proposed control point matches the way the organization already manages identity, data and application behavior. A company with a large Oracle footprint may find value in consolidating authorization, business constraints, governed APIs and application artifacts around systems it already operates. A company whose data is distributed across multiple database technologies may instead face a harder integration problem: the controls may be strongest inside the Oracle boundary, while agents still need to cross other databases, services and identity domains. In that case, the relevant comparison is not between “secure AI” and “insecure AI,” but between Oracle’s integrated enforcement model and the controls already available in the organization’s existing platform layers.
A serious evaluation should begin with adversarial, end-to-end tests rather than a feature demonstration. Teams should ask whether a user or agent can bypass a row-, column- or cell-level restriction through an alternate application, analytics path, API or generated query. They should test whether a business rule remains effective when the agent makes a write through a different interface, and whether the same identity context is preserved when work moves between an application, a data service and an agentic workflow. An expense agent, for example, should be tested against a limit it is not allowed to exceed, an employee-data workflow should be challenged with a request for a sensitive field, and a broad update should be rejected even when the request is phrased as a legitimate operational task. The expected result should be demonstrable enforcement, not merely a model refusal.
The review should also measure the operational evidence produced when controls work or fail. Security and compliance teams will need to know which identity initiated an action, which policy applied, what the agent attempted, what was blocked and what finally changed. Those records must remain useful across applications rather than disappearing inside an individual agent’s logs. Latency belongs in the same test plan. A policy that is technically correct but adds unpredictable delay to routine reads or writes may encourage teams to create exceptions, weakening the architecture it was meant to protect. Cross-application consistency matters for the same reason: a permission rule that holds in one interface but not another is not a reliable enterprise control.
The financial and strategic questions are less visible in a product announcement but just as important. Buyers should identify which capabilities require particular Oracle database, application or development editions, how licensing changes as agent traffic grows, and what effort is required to migrate existing policies and business logic. They should ask whether governed data access depends on Oracle-specific APIs, how much of the application representation can be reviewed or moved elsewhere, and whether models can be changed without redesigning the surrounding control plane. APEXlang may make generated applications easier to inspect, version and validate before import, but the resulting artifact still belongs to a broader Oracle workflow that an organization may become increasingly dependent on.
Model portability deserves a direct test. The architecture’s stated value is that permissions and business rules remain enforceable when the model or agent changes, so teams should verify that claim by running comparable workflows with different models and agent implementations. If changing the model preserves the same data boundaries, write restrictions, audit trail and approval points, the controls are doing work below the model layer. If portability depends on Oracle-specific tooling, prompt conventions or a narrow set of supported paths, that dependency should be recorded as part of the platform decision. The same test applies to application portability: teams should determine whether the governed business objects and declarative artifacts can coexist with non-Oracle services or whether they create a new center of gravity.
For Oracle-heavy enterprises with sensitive data, established APEX practices and a clear need for controlled agent access, Deep Trust AI Architecture is worth testing as an architectural proposition. Its promise is strongest when the database and platform can enforce the same rules across conventional applications and newer agentic paths. For organizations outside that ecosystem, the prudent next step is a control-by-control comparison with the database authorization, API gateway, identity and application-governance mechanisms already in place. The decision should rest on tested policy enforcement, auditability, performance, migration effort, licensing and portability—not on the presence of AI in the product name. That evidence will show whether Oracle’s deeper integration reduces operational risk or simply moves more of the enterprise’s dependency into one vendor’s stack.
Related articles
OpenAI’s Agents API: What Changes for Teams Building Long-Running AI Workflows
OpenAI’s public-beta Agents API packages the Codex harness, persistent sessions, tool orchestration, subagents, and managed or self-hosted sandboxes. The practical question is not whether it can run an agent, but whether its boundaries fit your workflow, budget, and data controls.
Bun’s Rust rewrite is not just a Rust versus Zig story
Bun turned a million-line language migration into a public test of AI-assisted open source engineering. The useful lesson is about tests, CI and human ownership.
Oracle’s Acceleron Network Puts AI Cluster Failure Recovery on the Critical Path
Oracle’s latest OCI networking announcement is less about faster links than about keeping distributed AI jobs moving when paths fail. The change shifts part of AI reliability work into the network fabric—and gives infrastructure teams a new design review checklist.
AlphaGenome Atlas turns nine billion possible DNA changes into a research map
Google DeepMind’s new AlphaGenome Atlas precomputes predicted molecular effects for every possible single-letter change in the human genome. Its value is practical: it helps researchers decide what to test next, while leaving diagnosis and clinical interpretation to experiments and genetics professionals.

Comments
Sign in to comment.
No comments yet.