AWS Transform Converts Azure .NET Code, but Migration Still Needs an Architecture Review
AWS Transform can now translate selected Azure SDK calls into AWS equivalents for modern .NET applications. The useful question is not whether the generated code compiles, but whether identity, data behavior, failure handling and operations still work after the cloud boundary moves.
AWS has added general availability for a code-conversion feature in AWS Transform that rewrites selected Azure SDK calls in modern .NET applications to their AWS equivalents. The announcement, published on October 16, covers Azure Functions to AWS Lambda, Azure Blob Storage to Amazon S3, and Azure Queue Storage to Amazon SQS. Azure Cosmos DB to Amazon DynamoDB is available as a preview conversion.
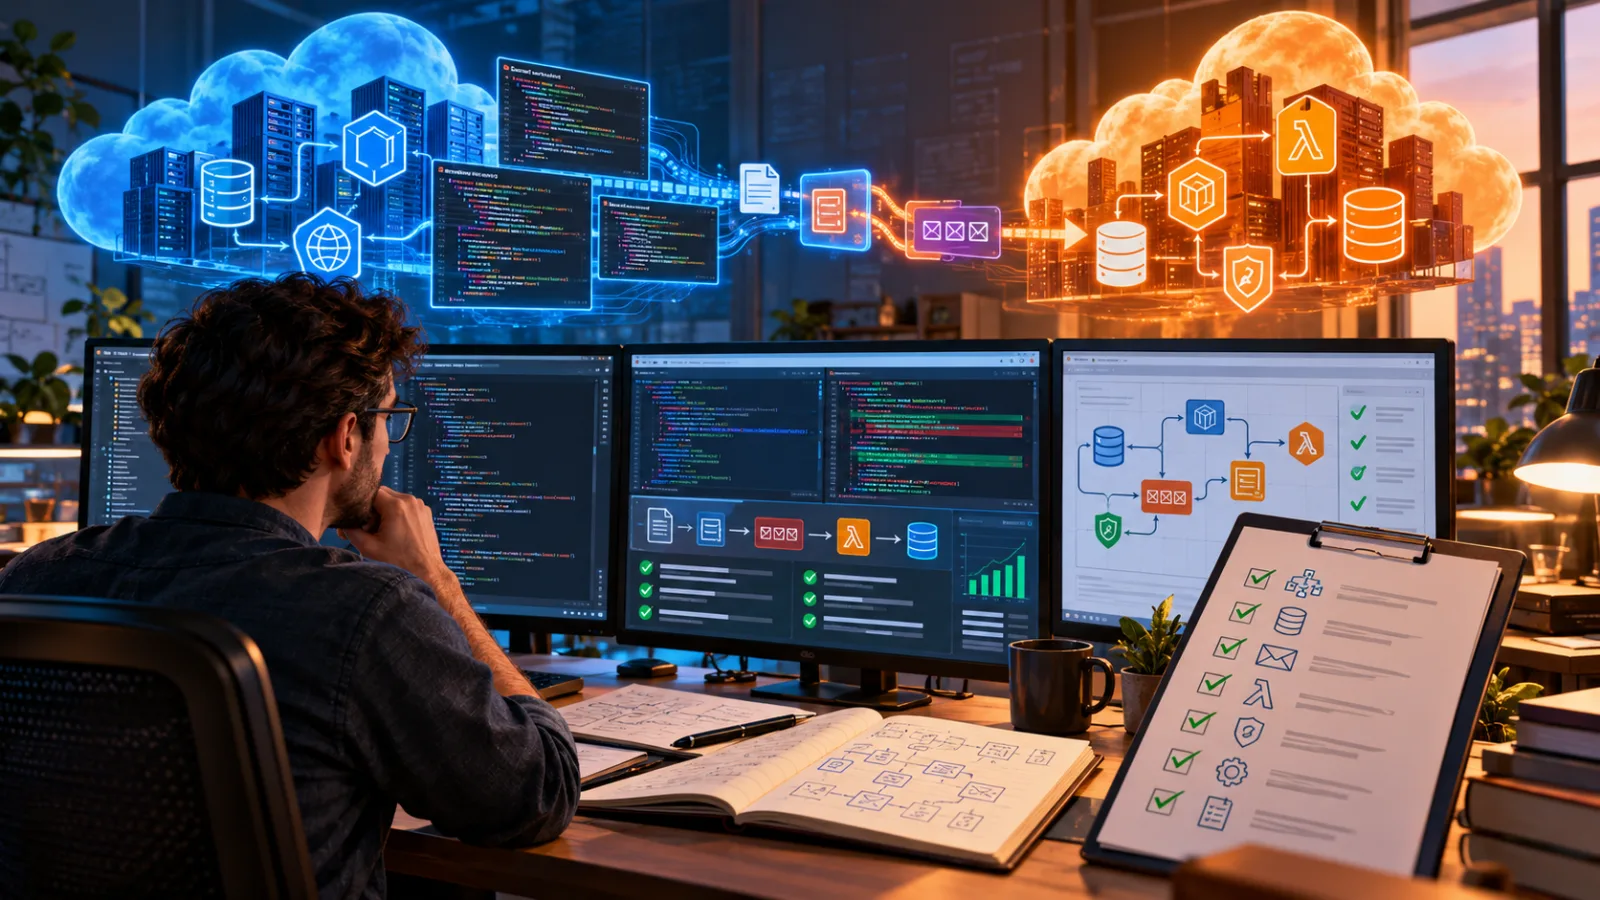
The immediate appeal is easy to understand: a team can submit an application that already works on Azure, let an agent identify supported cloud dependencies, and receive a transformed codebase rather than starting a service-by-service rewrite. The more important operational point is that this is source-code conversion, not a complete cloud migration. It does not recreate an Azure network, move data, reproduce identity policies, or prove that the resulting application has the same failure and consistency behavior.
That distinction should shape how platform and engineering teams evaluate the feature. Treat AWS Transform as an accelerator for a bounded modernization workstream, not as an approval to switch providers by accepting a generated pull request.
What AWS announced
AWS Transform’s .NET modernization agent can inspect submitted source code, identify Azure SDK usage, and include conversion choices in an assessment report and modernization plan. The team can accept those choices, change them, or opt out before the transformation runs.
The generally available mappings are deliberately narrow:
- Azure Functions can be converted to AWS Lambda functions.
- Azure Blob Storage SDK calls can be converted to Amazon S3 SDK calls.
- Azure Queue Storage calls can be converted to Amazon SQS calls.
- Azure Cosmos DB to Amazon DynamoDB conversion is listed as a preview capability.
AWS says the feature is available in eight regions: US East (N. Virginia), Asia Pacific (Mumbai, Tokyo and Seoul), Asia Pacific (Sydney), Canada (Central), and Europe (Frankfurt and London). The documentation also makes an important limitation explicit: the capability converts application code and does not handle cloud infrastructure migration.
That limitation is not a footnote. In a real service, the SDK is only one layer of the provider dependency. An Azure Function may rely on a hosting plan, managed identity, application settings, private endpoints, deployment slots, event bindings, storage accounts, Key Vault references, monitoring rules, and network restrictions. Replacing a namespace and a method call leaves those surrounding assumptions to be discovered and rebuilt by people.
The AWS feature therefore addresses a recognizable part of the migration cost: translating provider-specific application code. It does not remove the need to define the target architecture.
Why “equivalent service” does not mean equivalent behavior
Cloud service names encourage false symmetry. Blob Storage and S3 are both object stores. Azure Queue Storage and SQS are both queue services. Azure Functions and Lambda are both serverless compute platforms. At the API level, those comparisons are useful. At runtime, they are incomplete.
The first question for a migration team is not whether a method can be translated. It is whether the application’s contract survives the translation.
Object storage is a good example. A code path may upload an object, set metadata, generate a temporary URL, and then assume a particular visibility delay, overwrite behavior, checksum convention, or authorization model. The target service may support an analogous operation while using different defaults, headers, error types, lifecycle mechanisms, or policy vocabulary. A mechanically converted call can compile and still change the behavior that downstream systems observe.
Queues create a similar problem. A producer and consumer are coupled by more than a send method. They depend on delivery semantics, visibility timeouts, retention, maximum message size, ordering expectations, dead-letter behavior, redrive policy, duplicate handling, and retry timing. A conversion from Azure Queue Storage to SQS can produce valid AWS calls without proving that the consumer remains safe under redelivery or that an existing poison-message workflow still works.
Functions add another layer. An Azure Function may be triggered by an HTTP request, a queue, a timer, an event stream, or a binding that hides provider-specific plumbing. Lambda has its own event sources, invocation modes, concurrency controls, timeout limits, deployment packaging, permissions, and observability model. If the original application assumes a long-lived process, local filesystem persistence, a particular warm-up pattern, or a binding-generated request shape, the target implementation needs design work beyond SDK translation.
The practical result is simple: compile success is an early signal, not a migration acceptance criterion.
The right reading of the assessment report
AWS Transform’s workflow is useful because it puts conversion decisions before the transformation. That creates a point where a team can review the proposed target instead of discovering every choice after code generation.
Use that report as a dependency inventory with opinions attached.
Start by separating three categories:
- Directly supported calls. These are SDK references that the tool says it can convert. They are candidates for automated transformation, not automatically correct outputs.
- Adjacent provider dependencies. These include identity, configuration, networking, deployment, logging, tracing, secrets, event bindings, and infrastructure definitions. They may be visible in the same repository but are not covered by the listed service mappings.
- Business behavior. This includes idempotency, ordering, retention, authorization intent, data validation, recovery procedures, and user-visible error handling. It cannot be inferred safely from a one-to-one service mapping.
The report should also be reviewed for target-service choices. AWS documents default targets but allows teams to customize the plan, including opting out of some or all conversions and redirecting a default mapping. That matters when the target architecture is not a literal service substitution. For example, a team may choose to keep an object-oriented interface in the application while introducing a storage adapter, or it may decide that a queue workload belongs on a different integration service after measuring throughput and ordering requirements.
A useful review artifact is a table with one row per provider-specific dependency:
| Dependency | Source behavior | Proposed target | Behavior to prove | Owner |
|---|---|---|---|---|
| Blob upload | overwrite, metadata, retention | S3 operation | consistency and policy behavior | storage team |
| Queue receive | retry and visibility rules | SQS receive flow | duplicate and poison-message handling | service team |
| Function trigger | event shape and timeout | Lambda invocation | timeout, concurrency and retries | platform team |
| Identity | managed identity and scopes | IAM role and policies | least privilege and rotation | security team |
The purpose is not bureaucracy. It prevents a generated diff from becoming the de facto architecture document.
What the feature does well
There is a legitimate efficiency gain when the application uses supported Azure SDKs in conventional .NET code. The tool can find service references, offer a modernization plan, and rewrite known patterns at a scale that would otherwise consume developer time. It can also leave explicit markers where a conversion is unavailable, including TODO comments, stubs, or a next-steps document, according to the AWS documentation.
That is valuable in three situations.
The first is a portfolio assessment. An organization with many .NET services can use the analysis to discover how deeply each application is tied to Azure. The result can improve sequencing even when a service is not ready to migrate.
The second is a repetitive translation phase. Once the target contracts and infrastructure patterns are agreed, automated edits can remove a large amount of mechanical work. Engineers can spend more time on behavior and less time changing namespaces, client construction, and routine request shapes.
The third is a controlled modernization branch. A team can run the conversion against a copy of the application, compare the output with its existing abstraction boundaries, and use the resulting diff to identify code that should be isolated before a migration begins.
The feature is less useful when the repository is dominated by infrastructure-as-code, loosely documented bindings, custom Azure integrations, complex data access patterns, or application logic that treats provider behavior as part of the business contract. Those cases may still benefit from code analysis, but the conversion should not be mistaken for a complete migration plan.
The identity problem is bigger than a changed client constructor
Provider migrations often fail at the boundary between application code and authorization. Azure applications commonly use managed identities and role assignments. AWS applications use IAM roles and policies, with permissions attached to execution roles, task roles, instance profiles, or other identities depending on the runtime.
A converted SDK call has no authority by itself. The target deployment must provide an identity that can perform exactly the required actions on exactly the required resources. That means mapping not only “can read blob” to “can read object,” but also the scope, conditions, resource names, encryption keys, network path, and operational ownership of that access.
The migration review should answer:
- Which identity executes each function, worker, and deployment job?
- Which resource policy and identity policy together authorize the call?
- Does the target use customer-managed encryption keys, and who can use them?
- Can the workload reach the service through the intended network path?
- Are credentials short-lived and rotated without application changes?
- What is logged when an authorization check fails?
This is where a code-only conversion can create a misleading sense of completion. The application may compile, tests may pass with broad permissions, and the production deployment may still fail because the real policy boundary was never designed. Conversely, a quick fix that grants a wide role can make the migration “work” while increasing blast radius.
The security acceptance test should therefore include denied actions, cross-resource access attempts, and deployment from a clean environment. A migration is not complete when the happy-path request succeeds; it is complete when the target identity model is understood and constrained.
Data movement and data semantics remain human work
AWS Transform does not move the data behind Azure Blob Storage, Azure Queue Storage, or Cosmos DB. That sounds obvious, but it changes the project schedule. Code conversion and data migration can proceed in parallel only after the team has defined how the two versions coexist.
For object data, the plan needs a source inventory, size and object-count estimates, metadata and tag handling, encryption requirements, retention rules, access logs, and a cutover strategy. A copy that preserves bytes but loses metadata can still break consumers. A cutover that changes URL generation or authorization semantics can break clients even when every object arrived successfully.
For queues, copying messages is rarely a neutral operation. The team must decide whether old messages should be drained, replayed, discarded, or translated. A replay can trigger side effects twice. A drain can extend the migration window. A dual-write design can create divergence if one provider accepts a message and the other rejects it. The safer choice depends on the workload’s idempotency and business consequences.
For databases, the preview status of Cosmos DB to DynamoDB is a signal to be especially cautious. NoSQL systems often differ in partitioning, indexing, consistency, transaction scope, query language, item limits, and change-feed behavior. A converted data-access layer does not establish that the target data model will scale or return the same results. Teams should model representative access patterns and run data-quality checks before committing to a live cutover.
The migration plan should name the source of truth at every stage. “The data is in both clouds” is not a consistency strategy.
Testing should compare contracts, not just outputs
A conventional unit-test suite may verify that the converted code returns expected values from mocked clients. That is necessary but insufficient because mocks usually preserve the abstraction designed by the original provider.
A stronger test plan has several layers.
Contract tests verify the application’s own expectations: message schemas, object metadata, authorization decisions, retry handling, and error classification. These tests should run against the target services where behavior matters.
Differential tests exercise equivalent workloads against the source and target implementations and compare business-level outcomes. The comparison should not demand identical provider errors or request IDs. It should check what users, downstream services, and operators rely on.
Failure tests inject throttling, timeouts, partial writes, duplicate delivery, expired credentials, unavailable dependencies, and malformed events. The goal is to expose where the source and target failure models diverge.
Operational tests validate logs, metrics, traces, alarms, dashboards, and runbooks. A migrated service that works but cannot be diagnosed is not ready for production.
Security tests confirm least-privilege policies and verify that the workload cannot read, write, or invoke resources outside its intended boundary.
For serverless workloads, include concurrency and cold-start behavior, timeout margins, event-source retries, and deployment rollback. For queues, measure visibility timeout against the actual processing distribution rather than selecting a familiar value. For object storage, test metadata, encryption, conditional writes, and access URLs. For database conversion, replay real query shapes and compare pagination, consistency, and failure handling.
A safer migration sequence
A team evaluating the new capability can reduce risk by narrowing the first project.
Choose one service with a clear owner, a limited number of supported provider dependencies, and a testable rollback. Avoid starting with the system that combines identity federation, event fan-out, regulated data, and undocumented operational procedures.
Before running the conversion, create a source dependency map. Include SDK packages, environment variables, bindings, deployment manifests, secrets, network endpoints, data stores, queues, scheduled triggers, and monitoring integrations.
Then define the target contracts. Decide how the application will represent storage, messaging, configuration, identity, and telemetry. If provider-specific calls are scattered throughout business logic, introduce or strengthen adapters before conversion. This increases preparation work but makes the resulting diff easier to review and future changes less expensive.
Run the assessment and review every proposed mapping. Record intentional opt-outs. Treat unsupported calls as planned work, not as cleanup that can be left for the end.
Create the target infrastructure separately. Use narrowly scoped IAM roles, encrypted resources, private connectivity where required, logging, alarms, backups, and deployment controls. Do not use the generated application code as a substitute for infrastructure review.
Convert the code in a branch, compile it, and run static analysis. Then test against real target services with representative data and failure injection. Keep the source implementation available until the migration’s business and operational contracts are proven.
For cutover, prefer a reversible sequence: deploy dark, validate reads, exercise non-destructive writes, compare telemetry, shift a small amount of traffic or workload, and define the rollback trigger before increasing the share. The exact mechanism will differ by application, but the principle is constant: conversion should shorten the mechanical phase without shortening the evidence phase.
The governance question for platform teams
AWS Transform changes the economics of code translation, which means more organizations may be able to attempt provider migrations with smaller teams. That is useful, but it can also move risk earlier in the process. When code transformation becomes inexpensive, architecture decisions and validation become the scarce resources.
Platform teams should establish a standard review gate for generated migrations. It should require:
- a complete inventory of converted and unconverted provider dependencies;
- an approved target architecture and identity model;
- a data migration and rollback plan;
- tests for provider-specific semantics and failure behavior;
- evidence that observability and incident response work in the target;
- a human owner for every unresolved TODO or stub;
- a documented decision for any default mapping that was changed.
The gate should be proportionate. A small internal function that stores non-sensitive objects does not need the same process as a regulated transaction service. But both need a named owner and a way to prove that the converted behavior is acceptable.
The key policy is to keep generated code reviewable. Store the assessment report, modernization plan, transformation diff, test evidence, and exceptions with the service’s change record. If the conversion is rerun later, the team should be able to explain what changed and why.
What to watch next
The current announcement covers a focused set of Azure-to-AWS mappings and keeps Cosmos DB to DynamoDB in preview. That suggests AWS is starting with common, recognizable translation points rather than claiming universal portability.
Teams should watch for changes in supported .NET versions, additional Azure services, infrastructure handling, and the way the tool reports uncertain conversions. They should also watch their own test results. A pattern that appears equivalent in a small service may behave differently at higher volume, under retries, or with stricter identity policies.
For now, the practical advice is to use AWS Transform where it is strongest: inventorying dependencies and accelerating repetitive code changes. Keep architecture, data, identity, and production acceptance under explicit human review. The feature can make a migration branch appear quickly. It cannot make the two clouds share the same contracts.
That is the decision platform teams need to make before approving the first pull request: not “did the agent convert the code?” but “what evidence shows that this service still behaves correctly, securely, and operably after the provider boundary moves?”
Related articles
AWS fixes read-only bypasses in database MCP servers: what operators need to check
Two AWS security bulletins published on September 9 expose a recurring design problem in database-connected MCP tools: a text filter is not an authorization boundary. Here is who is affected, what the disclosures actually say, and how to contain the risk.
AWS Lambda MicroVMs make AI-agent sandboxes easier to deploy—and harder to govern by accident
AWS’s new Lambda MicroVM reference architecture gives teams fast, isolated execution environments for AI-agent tasks. The important change is operational: identity, egress, persistence, observability and cleanup now need to be designed as one system.
Cloud bills are production systems now
AWS’s impossible Cost Explorer estimates were not real charges, but they exposed a serious operational problem: cost alerts now belong in incident response.
La nouvelle expérience de développement d’AWS réduit les frictions du cloud — et rend indispensable une première revue de gouvernance
AWS simplifie l’arrivée dans le cloud avec des projets préconfigurés, des permissions gérées, la connexion d’agents de programmation et des plafonds de dépenses. Cette rapidité impose toutefois de vérifier immédiatement les identités, la région, les quotas et les accès générés.
Comments
Sign in to comment.
No comments yet.