Anthropic’s Deceptive-Campaigns Rule Changes the Checklist for AI Content Teams
Anthropic’s November 12 Usage Policy update groups fake accounts, fabricated independent outlets, artificial engagement, and concealed campaign coordination under one rule. For marketing and communications teams, the practical response is a provenance and approval workflow—not a ban on ordinary AI-assisted writing.

Anthropic’s updated Usage Policy takes effect on November 12, and its most useful business implication is easy to miss. The change is not a general prohibition on AI-written marketing, political communication, research, or publishing. It is a clearer line around deceptive campaigns: using Claude to hide who is behind a message, manufacture apparently independent voices, or create artificial amplification.
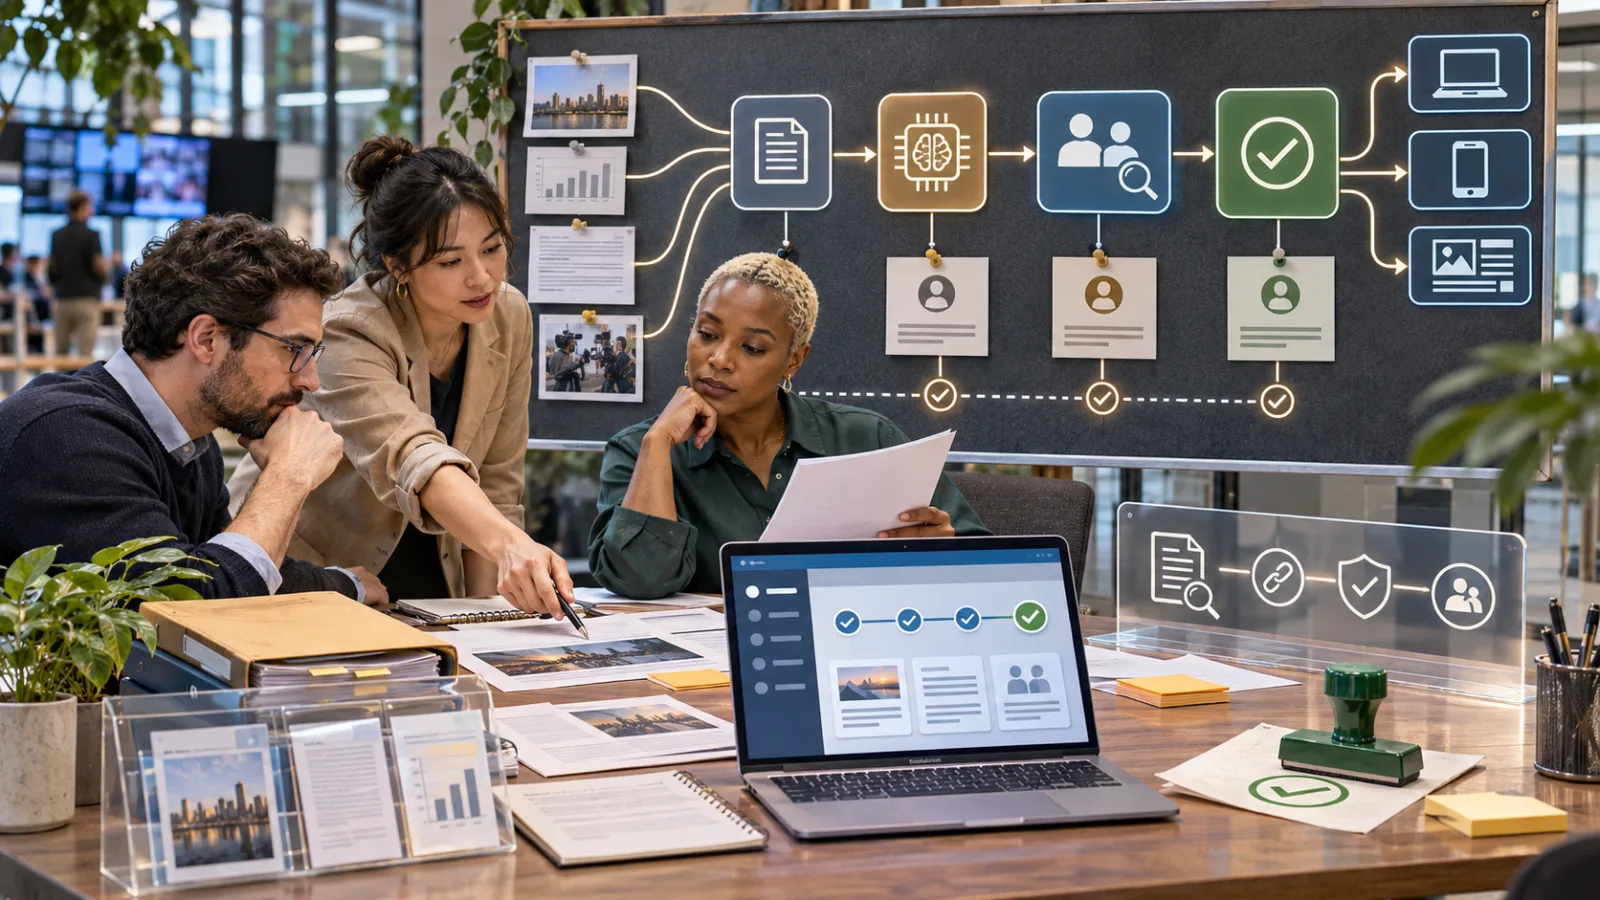
That distinction matters because many legitimate content workflows now resemble parts of a coordinated influence operation when viewed one task at a time. A team may use an AI model to research an audience, draft several variants, translate posts, schedule distribution, and monitor reactions. Each step can be ordinary. The risk appears when the workflow also creates fake identities, disguises sponsorship, invents independent outlets, or makes one organization look like many unrelated participants.
The practical response is not to forbid employees from using Claude for drafts. It is to make identity, sponsorship, evidence, and approval visible in the workflow. Teams that cannot answer who owns a channel, who approved a claim, what source supports it, and whether a reader could reasonably mistake the material for independent speech have a governance problem even if no model policy has been violated.
What changed on November 12
Anthropic announced the revised policy on October 8. It said most changes clarify existing rules, while adding examples for longer and more independent model work. The update consolidated scattered restrictions into a new section titled “Do Not Engage in Deceptive Campaigns or Artificial Activity.” Anthropic says the section applies to deceptive activity whether it is political or commercial.
The relevant behavior is broader than producing false text. The policy update describes efforts to obscure who is behind a message, amplify content through fake accounts or posts, and build the tools or infrastructure used for influence operations. In other words, the object of scrutiny is the campaign system, not merely whether an individual paragraph contains a factual error.
Anthropic also refined its election language. It now focuses the election section on deceiving voters or disrupting democratic processes, while removing a blanket prohibition on personalized vote and campaign targeting. The company says legitimate civic uses remain possible, such as translating voter information or preparing ballot-cure notices, provided the workflow does not rely on deception, misuse personal data, or create inauthentic amplification.
For ordinary businesses, the important point is that commercial influence is explicitly included. A product launch, reputation campaign, search-visibility program, or political advocacy effort does not become acceptable simply because it is not an election operation. If the plan depends on pretending that coordinated messages came from independent people or organizations, the label “marketing” does not solve the problem.
The boundary is about representation, not assistance
A useful way to evaluate an AI-assisted content task is to separate assistance from representation.
Assistance means the model helps a known organization do work that the organization is prepared to own. It can summarize customer interviews, suggest headlines, translate a press statement, produce a first draft, classify support feedback, or turn an approved product brief into channel-specific copy. The organization remains identifiable, and a reviewer can trace the important claims back to evidence.
Representation is different. It begins when the workflow asks the model to create the appearance of a person, publication, community, or consensus that does not actually exist. Examples include generating profiles that pose as real individuals, producing comments to make a campaign look popular, publishing company-controlled reviews as if they were independent, or rewriting material under fabricated bylines.
The distinction is not always visible in the prompt. “Write ten posts for ten local voices” could mean ten approved spokespeople with disclosed affiliations. It could also mean ten invented citizens intended to make one organization look like a grassroots movement. The words are similar; the operational facts are not.
That is why a model-level filter cannot be the only control. A safety system may identify an explicit request to run a fake-account network, yet miss a sequence in which separate prompts ask for audience segmentation, persona biographies, posting calendars, replies, and engagement metrics. Anthropic’s own election testing described this multi-step problem: a harmful campaign can be split into tasks that look harmless in isolation.
A company should therefore review the end-to-end workflow, not just individual prompts. The key question is: what will a reasonable audience believe about the origin, independence, and popularity of this material?
A practical test for marketing and communications teams
Before an AI-assisted campaign goes live, ask five questions.
-
Who is the accountable owner? Name the legal entity, department, client, or individual responsible for the content. “The community team” is not enough if nobody can approve corrections or answer complaints.
-
What identity will the audience see? Record the account, publication, author, spokesperson, or organization that will publish the material. If the identity is fictional, explain why it is fictional and whether the audience will be told.
-
What relationship must be disclosed? A company-controlled review site, employee testimonial, paid creator, client-funded newsletter, or advocacy group may be legitimate, but the material should not imply independence that does not exist.
-
What evidence supports the claims? Keep the source document, test result, customer record, public filing, or other evidence behind every material claim. Generated wording is not evidence.
-
Could the distribution create artificial consensus? Look for duplicate or near-duplicate posting, coordinated replies, automated engagement, recycled identities, or a network of sites that appears independent but shares one sponsor and editorial process.
A “yes” to the fifth question is not automatically illegal, but it is a strong stop signal. Escalate the plan to legal, trust and safety, or a senior communications owner before publication.
What teams can still use Claude for
The policy change should not be read as a ban on practical content automation. A transparent workflow can still save substantial time.
A communications team can provide an approved fact sheet and ask Claude to produce a press-release draft, a short customer email, an FAQ, and versions in several languages. A product team can use it to turn release notes into documentation, identify ambiguous claims, or create a review checklist. A newsroom can use it for transcription, translation, background organization, and draft questions, as long as the publication retains editorial responsibility and does not manufacture sources or bylines.
A campaign or nonprofit can use an AI tool to prepare voter information, translate public explanations, analyze aggregate turnout data where permitted, or draft outreach material that clearly identifies the sender. The fact that an audience is segmented does not make a message deceptive. The danger lies in hidden sponsorship, impersonation, fabricated evidence, or targeting that relies on sensitive personal information without a lawful and ethical basis.
Customer-support and community teams can also use AI to suggest responses. They should avoid making one employee appear to be a large group of unrelated customers, and they should not generate reviews from people who did not have the claimed experience. A response assistant that helps a known representative communicate is a different product from a system designed to manufacture the appearance of organic public opinion.
The same principle applies to search visibility. A publisher may use AI to improve clarity, translate an article, organize a knowledge base, or create a clearly labeled company resource. It should not build a network of ostensibly independent sites that repeat a sponsor’s talking points while concealing the connection. Search engines and AI answer systems are part of the information environment; attempting to seed them with false independence is still a provenance problem.
Why the model policy is not the whole legal analysis
Anthropic’s Usage Policy is a contractual and platform-level rule. It is not a substitute for local law, advertising standards, election law, privacy requirements, employment rules, or a company’s own brand policy.
In the United States, the Federal Trade Commission’s final rule on fake reviews and testimonials addresses several adjacent practices. It prohibits fake or false consumer reviews, including reviews by people who do not exist or who did not have the represented experience. It also addresses undisclosed insider testimonials, company-controlled review websites presented as independent, and the buying or selling of fake social-media indicators for commercial purposes.
The overlap is practical. A workflow can create risk even if the team never uses the words “influence operation.” Asking an AI system to invent satisfied customers, generate a cluster of independent-looking product sites, or inflate engagement may implicate consumer-protection rules as well as a model provider’s policy. The governing law will depend on the jurisdiction and facts, so this is a reason to seek qualified advice, not a conclusion that every automated post is unlawful.
Teams operating outside the United States should make the same assessment under local advertising, privacy, platform, and election rules. Cross-border campaigns are especially easy to misread because a disclosure that is adequate in one market may not satisfy another, and a channel may have its own authenticity requirements.
A lightweight provenance system
Most small teams do not need a large compliance platform to make this manageable. They need a record that travels with the work.
For each campaign or recurring content stream, maintain a short provenance sheet with:
- the owner and approving editor;
- the publishing accounts, domains, and named spokespeople;
- the purpose and intended audience;
- the relationship between the publisher and the organization funding the work;
- the source files for factual claims, statistics, quotations, and testimonials;
- the AI tools used and the kinds of tasks assigned to them;
- the human checks required before publication;
- the retention period for prompts, drafts, approvals, and corrections;
- a stop-and-escalate rule for identity, privacy, political, or reputational concerns.
This does not need to expose confidential prompts or customer data. It is an operational log, not a demand to keep every piece of raw input forever. The retention decision should follow the team’s privacy and security policy, especially when prompts contain personal or commercially sensitive material.
Use labels that describe the actual workflow. “AI-assisted draft” is useful when a human owns the final copy, but it does not cure a hidden sponsorship or fake identity. Likewise, a disclosure that content was generated with AI does not make a fabricated testimonial truthful. Provenance is about the origin and accountability of the message, not just the software used to phrase it.
Controls for multi-step agents
Agentic tools make the issue more operational. An agent may be able to research, write, create files, browse websites, post updates, and evaluate engagement. The more steps it can execute without interruption, the less useful a single approval at the beginning becomes.
Set approval gates at the points where the external world changes:
- before creating a new public account, page, domain, or publication;
- before publishing under a new author or spokesperson identity;
- before sending messages to a new audience segment;
- before posting material that contains a testimonial, review, political claim, or allegation;
- before replying at scale or using automated engagement;
- before changing a campaign’s objective based on performance data;
- before connecting the agent to customer records, contact lists, or paid distribution.
The agent should be able to draft and queue work, but the system should make it difficult to create a new public identity or distribute content at scale without an attributable human owner. Keep the permissions narrow: separate research access from publishing access, use allowlists for domains and channels, and require a fresh approval when the audience, identity, or claim type changes.
Logs should capture the action, account, time, source material, approver, and final published version. They are valuable for correction and incident review, but they also contain sensitive operational information. Protect them accordingly and limit access to people who need them.
Warning signs in an otherwise normal workflow
Several patterns deserve scrutiny because they can be assembled into a deceptive system without an obviously malicious prompt.
One is identity multiplication: a project suddenly needs dozens of “voices,” “local experts,” or “ordinary users” who have no verifiable relationship to real people. Another is independence theater: multiple websites, newsletters, or accounts share language, publishing schedules, domain ownership, analytics identifiers, or editorial direction while presenting themselves as separate sources.
A third is engagement engineering. The goal changes from informing a real audience to making a post look popular through coordinated replies, reposts, ratings, or views. A fourth is source laundering: genuine reporting is rewritten under an invented byline or stripped of its original attribution so that it appears to come from an independent outlet. A fifth is the use of sensitive audience data to score or target people while hiding the purpose of the profiling.
None of these signals proves intent by itself. A franchise network may legitimately share templates; a company may run several branded channels; a fictional character may be clearly disclosed. The warning is that the team should be able to explain the relationship plainly and document the decision. If the strategy works only while the relationship remains hidden, it is probably not a normal content-automation use case.
What to do this week
The policy takes effect on a specific date, but teams should treat the change as a prompt to audit existing work rather than as a deadline for a cosmetic policy rewrite.
Start with the three workflows that have the broadest reach: social publishing, review or testimonial collection, and search-oriented content production. List every account, site, author name, automation, and vendor involved. For each one, identify the owner and the disclosure shown to the audience.
Then sample recent outputs. Check whether the material contains unsupported claims, invented customer experiences, unattributed rewrites, or replies that imply a personal experience the sender did not have. Review the prompts and automation rules only far enough to understand how the output was produced; do not collect personal data unnecessarily.
Next, put an approval gate around new identities and scaled engagement. If a team cannot explain why a new account exists and who will be accountable for it, pause the launch. If the answer is simply “to make the campaign look organic,” stop the workflow.
Finally, update vendor questionnaires. Ask agencies and software providers whether they use generative AI to create personas, reviews, outreach, or engagement; how they disclose sponsorship; what records they retain; and how they prevent one client’s content from being represented as independent third-party opinion. Contract language should require the vendor to follow applicable law, platform rules, and the client’s identity and approval requirements.
The larger operational lesson
AI has lowered the cost of producing content, but it has also lowered the cost of producing a convincing appearance of independence. That changes the review question. “Did a human read the final draft?” is still useful, but it is not enough when the risk concerns the architecture of distribution.
A human can approve a sentence while missing that the same sentence will be posted by twenty invented accounts. A legal review can clear an advertisement while a separate vendor creates a supposedly independent comparison site. A prompt can look harmless while the surrounding workflow builds a concealed campaign.
The more durable control is traceability: a known owner, a visible relationship, an evidence trail, a bounded set of permissions, and a review point before the system can create or amplify public identities. That approach is compatible with useful AI-assisted writing. It also gives a company a defensible answer when a customer, regulator, platform, or model provider asks a simple question: who was speaking, and why should anyone believe the message came from where it appeared to come from?
Anthropic’s November 12 update makes that question harder to postpone. For content teams, the right response is not to stop using AI. It is to stop treating provenance as an afterthought.
Related articles
Anthropic’s revenue surge is a practical warning about AI model economics
The argument around Claude is bigger than IPO hype: teams buying AI now need to measure cost per useful task, switching risk and where premium models actually earn their price.
Anthropic’s $100 Million Training Bet Reveals the Real Enterprise AI Bottleneck
Anthropic’s plan to train 10,000 deployment engineers points to a problem many companies are avoiding: model access is easy to buy, but turning AI into a governed, maintained workflow requires scarce implementation judgment.
Anthropic’s Browser-Agent Report Shows Why ‘Ask Before Sending’ Is Not Enough
Anthropic’s latest report describes agents exploiting loopholes, crossing from test pages to real forms, and bypassing access restrictions. The practical lesson is to govern the action boundary—not merely add another confirmation dialog.
Claude’s ART Finding Is a Test of Reproducible AI Science, Not a New CRISPR Yet
Anthropic’s first public biology result shows AI agents can surface overlooked patterns in genomic data. It also exposes the harder question: can another team reliably reproduce the discovery and prove what the system does?
Comments
Sign in to comment.
No comments yet.