EmbeddingGemma 2 makes local multimodal search practical, but it is not a drop-in RAG upgrade
Google’s new 740-million-parameter open-weight model puts text, code, images, video and audio in one embedding space. The useful question is not whether it is small, but where a unified local index improves a real workflow.
Google’s EmbeddingGemma 2 is a release aimed at a part of the AI stack that rarely gets attention outside engineering teams: the embedding model that decides which pieces of information a search or retrieval system sees first. It is not a chatbot, a general-purpose assistant, or a smaller replacement for a generative model. It converts text, source code, images, video frames and audio into vectors that can be compared for semantic similarity.
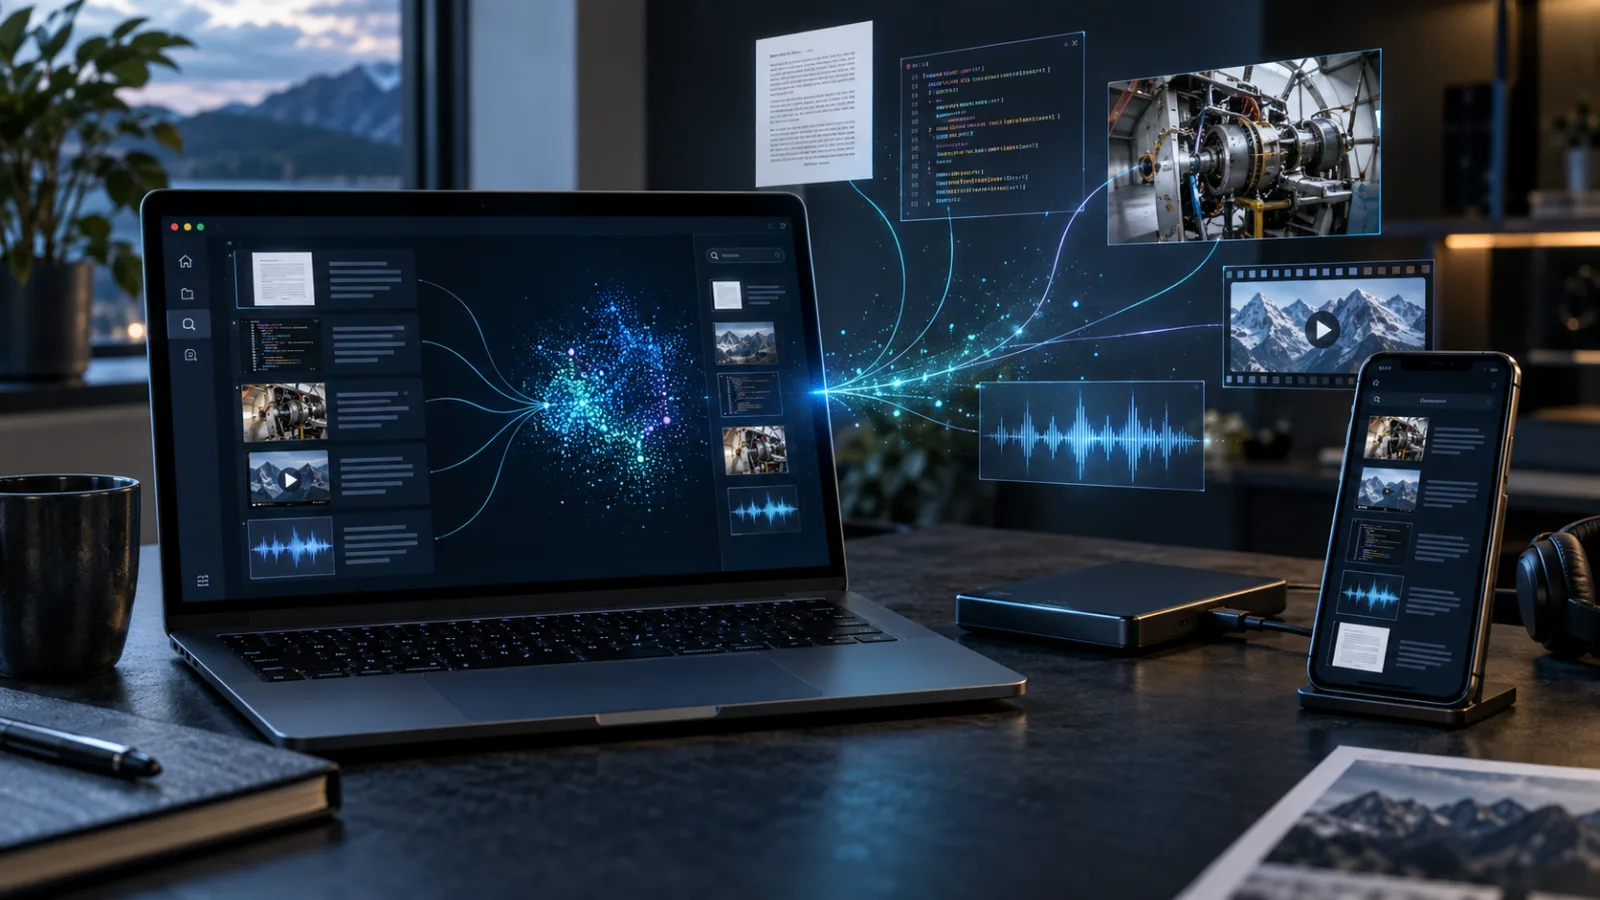
That distinction matters. A retrieval system can only answer well when its first-stage search returns the right material. If a team has documentation, screenshots, recordings, source code and product clips spread across separate stores, conventional text-only indexing forces every modality through a translation step. Images must be captioned, audio must be transcribed, and video must be reduced to selected frames before a text embedding model can see any of it. EmbeddingGemma 2 is designed to remove some of those translations by placing multiple media types in a shared 768-dimensional vector space.
The model was announced on October 6, 2026, by Google DeepMind and Google’s AI Edge teams. The official documentation describes it as a 740-million-parameter open-weight model built for unified multimodal embeddings, with modular variants that let developers load less than the full model when they only need text and code. Google says the model is released under the Apache 2.0 license and can run locally and offline on consumer hardware.
The release is worth watching because it targets a practical bottleneck: private, low-latency retrieval on devices that cannot host a large generative model. It is also worth approaching carefully. The model card, benchmark conditions, input formatting, quantization choices and index design will determine whether it improves a real application. A shared vector space is useful infrastructure, not proof that every cross-modal search problem has been solved.
What changed in EmbeddingGemma 2
The most important change from the first EmbeddingGemma release is the scope of the input space. EmbeddingGemma 1 was a lightweight text embedding model. EmbeddingGemma 2 extends the idea to text, code, images, video and audio, including combinations of those inputs. A description can be compared with a screenshot, a spoken phrase with a video frame, or a code query with a relevant source file without first converting everything into a single textual representation.
The official model documentation says that the system produces 768-dimensional vectors and supports context lengths of up to 8,192 tokens for text and source code. Google’s announcement describes a modular architecture ranging from a 270-million-parameter text-and-code configuration to the complete 740-million-parameter multimodal model. That distinction is more important than the headline parameter count. A developer building a local code search tool does not necessarily need the image, video and audio components in memory. A media library cannot assume that the text-only footprint will describe the full multimodal runtime.
The model also supports Matryoshka Representation Learning, or MRL. In practical terms, the output can be truncated to smaller dimensions such as 128, 256 or 512 instead of always storing all 768 values. This can reduce vector database storage and distance-computation costs, although the quality trade-off must be measured on the application’s own data. A smaller vector is not automatically a better vector, and the optimal dimension depends on recall requirements, index type and the distribution of the corpus.
Google reports a substantial improvement over the first model on the Code MTEB benchmark, moving from 68.76 to 78.68 according to its announcement. That is a useful signal for code search, but it should not be read as a universal ranking of all possible retrieval workloads. Benchmark gains on curated datasets do not tell a team whether its own issue tracker, monorepo, screenshots or support recordings will retrieve the right evidence.
The release also keeps the on-device emphasis of the original model. Google reports that quantized text-only weights can use about 191 MB of active RAM on a Pixel 11 Pro, while the complete multimodal model uses about 567 MB in the same reference setup. Those figures are attractive for mobile and edge applications, but they are measurements under a particular device, runtime and quantization configuration. They should be treated as planning numbers rather than a promise about every CPU, GPU, NPU or browser environment.
Why a shared embedding space is useful
Most retrieval systems are still assembled as a chain of specialized components. Documents go through a text embedder. Images are captioned or embedded separately. Audio is transcribed. Video is sampled into frames, then described or embedded. Search either stays inside one modality or depends on a second-stage system to connect results from different indexes. This architecture can work well, but it introduces extra latency, more failure points and more policy decisions about what information is safe to discard.
A unified embedding space changes the first question from “how do we translate this media into text?” to “what is semantically close to this query, regardless of its original format?” Consider a field-service application. A technician may search for a spoken description of a fault and expect to find a maintenance manual, a photograph of a damaged component and a short video showing the repair. A text-only pipeline could support this, but it needs transcription, image labeling and careful query expansion. A native multimodal embedder can make those relationships available earlier in the pipeline.
The same pattern applies to software teams. A repository may contain source code, API documentation, architecture diagrams, terminal recordings and screenshots from an issue. A developer asking for “the screen where the token refresh failure is shown” is not asking a purely textual question. A model that embeds code and images in a common space may let the retrieval layer find evidence that a text-only index would never surface.
There is also a privacy argument. If embeddings can be generated locally, a device does not need to upload personal photographs, recorded conversations or internal documents to a hosted indexing service just to make them searchable. Offline execution can reduce exposure and improve responsiveness in poor-connectivity environments. It does not make the entire application private by itself: logs, analytics, synchronization, model downloads and the generative model used after retrieval still need separate review.
The release is therefore less about “AI on a phone” as a slogan than about moving one specific piece of infrastructure closer to the data. A local index can support search-as-you-type interactions, private document retrieval, media organization and zero-shot routing without a round trip to an embedding API. Those are concrete gains when the device, runtime and corpus fit the model’s operating envelope.
The model is small enough to test, not automatically small enough for every product
A 740-million-parameter model is compact beside a modern generative model, but it is not weightless. Developers must account for model files, tokenizer and processor code, temporary activation memory, the vector index, the application itself and any downstream reranker or language model. Multimodal inputs also vary dramatically in cost. A text query, a high-resolution image, a long audio recording and a sequence of video frames are not equivalent units of work.
The modular design helps. Text and code applications can use the smaller configuration and avoid shipping unused encoders. A photo library may load vision support without enabling audio. An application that indexes occasional video can process frames in a background job rather than keeping every modality resident during interactive search. These choices are architectural decisions, not merely flags in an API call.
The reported memory figures are most persuasive for developers who already have a narrow local use case. A phone-based notes search tool, a desktop media catalog or an offline support assistant can measure whether a few hundred megabytes and local inference latency are acceptable. A large enterprise archive with millions of documents may still need a server-side indexing tier, batching, a distributed vector store and a separate policy for raw media retention.
Quantization adds another layer of judgment. It can make the model usable on more devices, but changes in numerical precision can affect similarity ranking. If the application returns only a handful of results, a small loss in recall may be visible immediately. If it uses a broad candidate set followed by a strong reranker, the same loss may be tolerable. The correct test is not whether the quantized model runs; it is whether the final product retrieves the right evidence at an acceptable cost.
The first practical test should be retrieval quality, not a demo
The easiest demonstration is cross-modal search: type a sentence, retrieve a matching picture, or show an image and retrieve related text. That is useful for confirming that the pipeline is wired correctly, but it says little about production quality. A team should build a small evaluation set before changing its index.
Start with real queries from the intended workflow. For a codebase, collect searches that developers actually make and mark the files that contain the answer. For a support archive, sample recordings, screenshots and documents that belong to the same incident. For a personal library, use natural descriptions rather than labels written by the developer. Include difficult negatives: visually similar images with different meanings, code files that share vocabulary but implement different behavior, and recordings whose transcript contains the right words while the relevant evidence is visible only in the video.
Measure recall at several cutoffs, not just whether the top result looks good. Recall at 5 or 10 tells you whether the downstream reranker has a chance to recover the answer. Track latency separately for indexing and interactive queries. Record memory use, battery impact and index size on the actual devices that matter. If the application supports multiple modalities, compare within-modality and cross-modality searches; a model can be strong at text retrieval while weaker at image-to-text or audio-to-code matching.
Input formatting deserves particular attention. The model guide describes task-specific usage through sentence-transformers and identifies the model as google/embeddinggemma-2. Embedding models often distinguish between a document, a query, a title and a passage through prefixes or structured prompts. If the corpus is indexed with one convention and the query is encoded with another, quality can fall without any obvious runtime error. Teams should keep the exact preprocessing, modality handling, dimensionality and normalization settings alongside the index version.
A minimal experiment might compare four configurations: the existing text-only embedder, EmbeddingGemma 2 using full 768-dimensional vectors, the same model with a reduced MRL dimension, and a quantized local build. Hold the corpus and query set constant. That experiment produces a more useful answer than a polished demo because it reveals whether the multimodal capability solves a real retrieval gap or merely adds another model to maintain.
Where developers should try it first
The strongest early candidates are applications where the user’s information is already mixed across formats and where sending that information to a hosted API is undesirable. A local-first knowledge base is one example. It can index Markdown, PDFs, screenshots and voice notes, then return related material without uploading the underlying files. The system still needs document parsing, OCR and perhaps speech recognition, but the embedding stage can provide a common retrieval layer after those inputs are available.
A desktop media organizer is another. Users can search a photo and find visually or semantically related text notes, or search with a phrase and find images and short clips. The local model is especially relevant when the library is personal, large and not suitable for cloud synchronization. The product should make clear whether embeddings are stored locally, whether thumbnails or original media leave the device, and whether any background service performs additional processing.
Developer tooling is a more technically demanding but promising area. An IDE or code browser could combine symbol-aware code chunks with issue screenshots, design references and recorded test sessions. The model’s reported code improvement makes it reasonable to test, but source code retrieval has constraints that generic semantic similarity does not capture. Names, imports, call relationships, version boundaries and exact error messages often matter more than broad conceptual similarity. A hybrid system that combines lexical search, symbol indexes and embeddings is likely to be safer than replacing all existing search with one vector index.
On-device intent routing is another use case mentioned in Google’s launch material. Instead of training a classifier for every small application, a developer can compare an input with a set of labels or descriptions and select the closest intent. This is attractive for offline commands and privacy-sensitive interfaces. It also needs conservative thresholds. A low-confidence match should fall back to clarification or a deterministic path rather than silently selecting a destructive action.
Video search may benefit from the shared space, but it is where cost assumptions can fail fastest. A long recording must be sampled, and the useful moment may sit between sampled frames or depend on speech. Embedding every frame at full fidelity can create a large index and expensive ingestion job. A practical system may combine transcript chunks, scene boundaries, selected keyframes and metadata, then use the multimodal model for candidate generation.
What not to assume from the launch
The first mistake would be treating “open” as a complete description of the release. EmbeddingGemma 2 has open weights and an Apache 2.0 license according to Google’s documentation, which is a favorable starting point for deployment and modification. The application still inherits obligations from its other dependencies, model-serving runtime, datasets and distribution channel. Teams should keep the model license with the exact weights they ship and review any additional Gemma terms or usage requirements attached to the selected artifact.
The second mistake would be assuming that a shared vector space makes modalities equally searchable. Cross-modal alignment is an optimization target, not a guarantee of identical quality across text, images, video and audio. Google’s published benchmarks provide evidence about selected tasks. They do not replace an evaluation set built from the application’s users, languages, image styles, recording conditions and domain vocabulary.
The third mistake would be using embeddings as a security boundary. A vector index can leak information through membership inference, nearest-neighbor results or poorly protected backups. Local storage reduces network exposure but does not protect a laptop from a compromised process or an unlocked device. Sensitive applications should consider encryption at rest, access controls, deletion behavior and whether vectors remain after the source file is removed.
The fourth mistake would be confusing retrieval with understanding. EmbeddingGemma 2 can help select relevant evidence; it does not verify that the evidence is current, authoritative or safe to act on. A local RAG assistant still needs source attribution, freshness rules, access filtering and a generative model that is instructed to distinguish retrieved facts from guesses. If the wrong screenshot or obsolete code path is retrieved, a fluent answer can make the failure harder to notice.
Alternatives and how to choose between them
The right comparison depends on the task. If an application only needs multilingual text search, the original EmbeddingGemma or another established text embedder may be cheaper and easier to validate. There is no reason to pay the complexity cost of multimodal support when the corpus and queries are text-only. Google’s own documentation positions EmbeddingGemma 1 as a separate previous version rather than requiring every user to migrate.
For server-side search, larger embedding models may still win on quality or language coverage, especially when memory and network access are not limiting factors. Hosted APIs can also be operationally simpler, though they introduce cost, latency, data-governance and service-dependency questions. A team should compare total system performance, not only model benchmarks: indexing throughput, query latency, storage, failure behavior and maintenance all matter.
Specialist pipelines remain sensible when the modality has domain-specific requirements. Optical character recognition can be better for exact text in documents. Audio transcription can expose searchable words and timestamps. Code intelligence tools can use parsers and language servers to understand symbols and references. EmbeddingGemma 2 may sit alongside those systems as a common semantic layer instead of replacing them.
Open multimodal models from other communities may offer different trade-offs in size, language support, runtime compatibility or licensing. The useful question is not which model has the strongest launch claim. It is whether the model can be run in the required environment, whether its license fits the product, whether the team can reproduce the preprocessing, and whether its errors are acceptable for the user’s task.
A sensible adoption plan
For an initial trial, pin the exact model revision and runtime. Do not build a production index from a moving “latest” artifact. Store the preprocessing configuration, output dimension, normalization rule and quantization settings with the index metadata. Create a small held-out test set before tuning the search threshold.
Then test one narrow workflow end to end. A useful pilot might be searching a few thousand internal documents and screenshots, or finding repair clips from a controlled set of recordings. Keep the generative answer layer out of the first measurement if possible. First prove that the retrieval layer returns the correct evidence. Only then measure whether a downstream assistant produces better answers.
Compare local and hosted baselines with the same queries. Include slow devices, background indexing and interrupted jobs. Check what happens when a source file is deleted, when a model update changes vector geometry, and when a user searches in a language or format underrepresented in the evaluation set. Treat re-indexing as an expected operation, not an exceptional disaster.
Finally, make the product’s boundaries visible. Tell users which data stays on the device, what is synchronized, how long embeddings remain, and whether an online model is called after retrieval. Provide a way to inspect the source behind a result. If the system is used for decisions, require confirmation when confidence is low or the retrieved evidence conflicts. Local inference can improve privacy and responsiveness, but transparency still has to be designed.
The larger significance
EmbeddingGemma 2 is an interesting open-source release because it focuses on the connective tissue of software rather than on a headline chatbot experience. The value of a multimodal embedding model appears only when a product has information that users need to connect: a question and a screenshot, a phrase and a recording, a function and an incident report. For those workflows, a compact local model could simplify indexing and make private retrieval available on devices that previously depended on a server.
The release is not a reason to replace a working search stack overnight. Its practical contribution is a testable option: one model family, several input types, local execution, open weights and a smaller deployment footprint than many general multimodal systems. That combination makes it worth trying in a bounded pilot, especially for private media search, mixed-format knowledge bases and edge applications.
The recommendation is straightforward. Start with a corpus where cross-modal retrieval solves a visible problem. Keep lexical, structural and specialist indexes where they provide exactness. Measure recall, latency, memory, storage and deletion behavior on real hardware. Review the license and model terms with the rest of the dependency tree. If EmbeddingGemma 2 improves the evidence reaching the user without making the system harder to understand, it has earned a place in the stack. If it only produces a more impressive demo, the smaller and simpler baseline is still the better engineering choice.
Comments
Sign in to comment.
No comments yet.